GRPO训练不再「自嗨」!快手可灵 x 中山大学推出「GRPO卫兵」,显著缓解视觉生成过优化 (opens in a new tab)
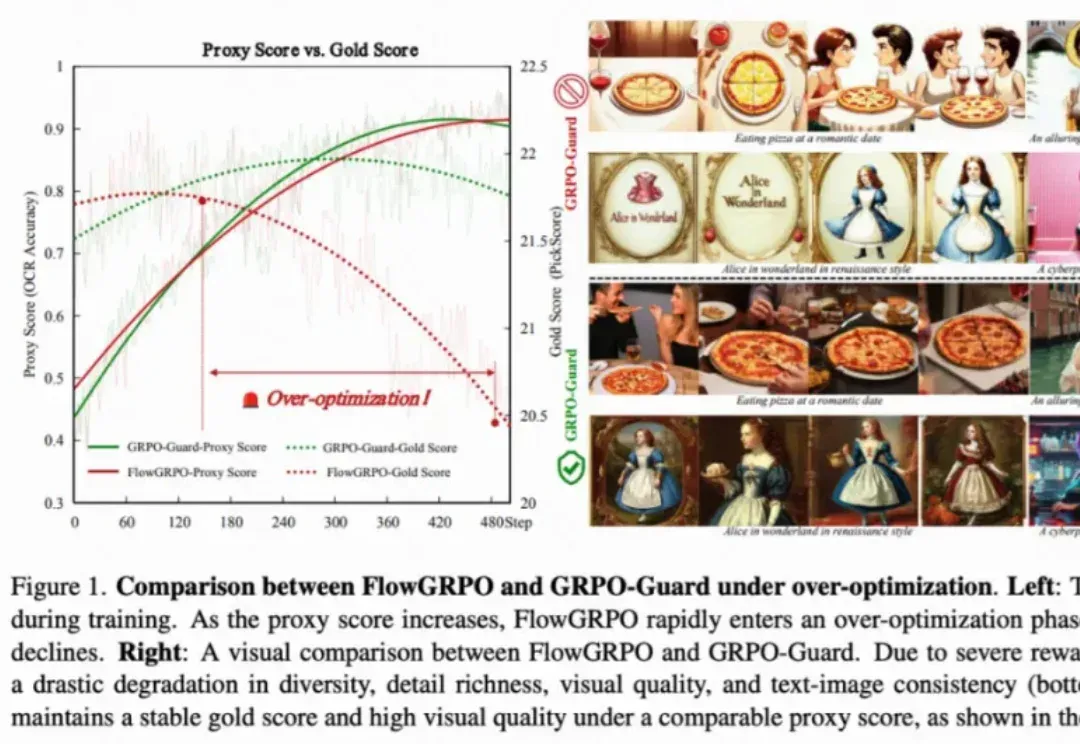
目前,GRPO 在图像和视频生成的流模型中取得了显著提升(如 FlowGRPO 和 DanceGRPO),已被证明在后训练阶段能够有效提升视觉生成式流模型的人类偏好对齐、文本渲染与指令遵循能力。
Total 126 articles
目前,GRPO 在图像和视频生成的流模型中取得了显著提升(如 FlowGRPO 和 DanceGRPO),已被证明在后训练阶段能够有效提升视觉生成式流模型的人类偏好对齐、文本渲染与指令遵循能力。
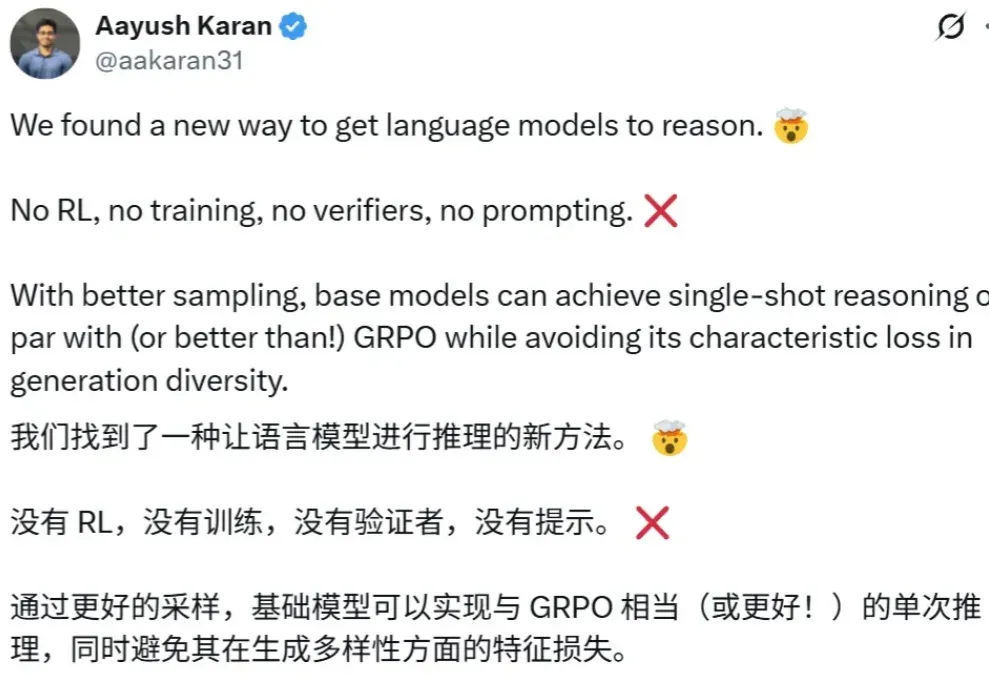
强化学习能力强大,几乎已经成为推理模型训练流程中的标配,也有不少研究者在探索强化学习可以为大模型带来哪些涌现行为。
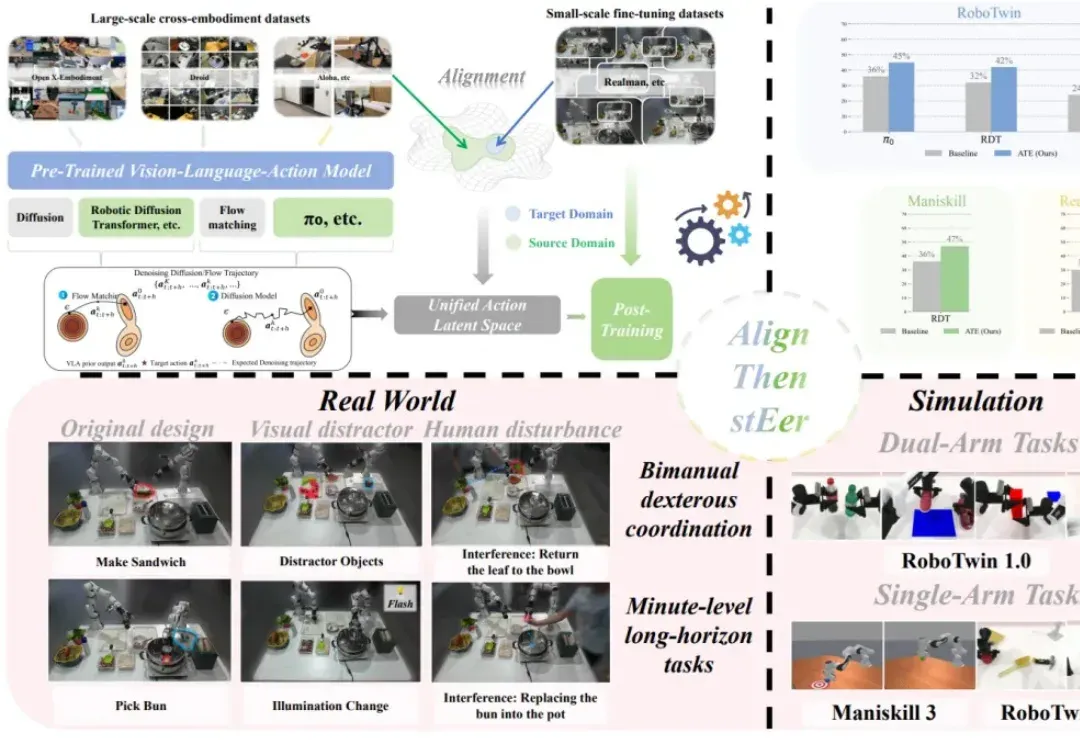
在多模态大模型的基座上,视觉 - 语言 - 动作(Visual-Language-Action, VLA)模型使用大量机器人操作数据进行预训练,有望实现通用的具身操作能力。
Jinyan Su draws on post-training research and job-search experience to discuss data vendors' tasks, sales and quality checks. This is personal observation and commentary; anonymous examples are not independently verified or representative of every provider.
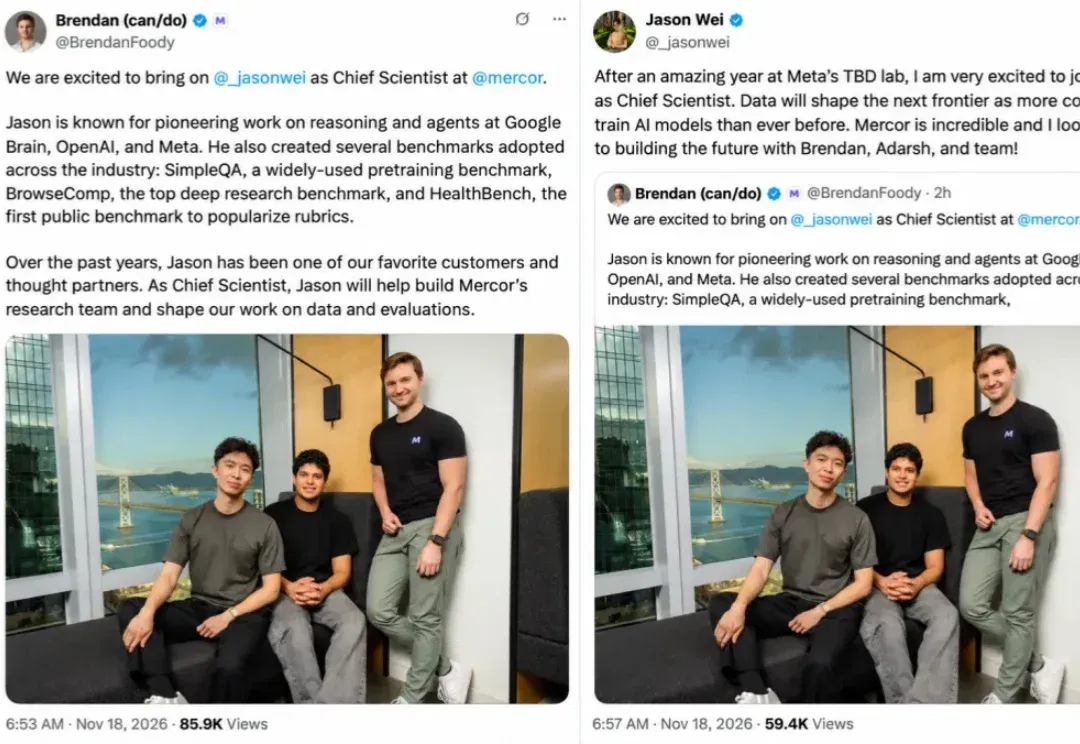
Jason Wei, first author of the chain-of-thought prompting paper, confirms he is leaving Meta for Mercor to work on data and model evaluation. The report traces his research career and Mercor's expansion from expert data services into evaluation and post-training infrastructure.
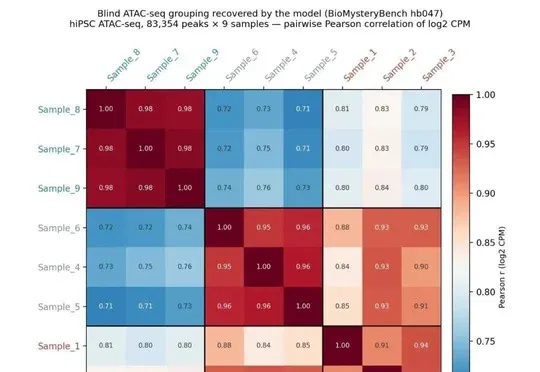
The team reports multi-attempt results for its bioinformatics post-trained Qwen model and shows cohort, unlabeled-sample and data-QC cases. Findings remain limited to the stated tasks and systems.
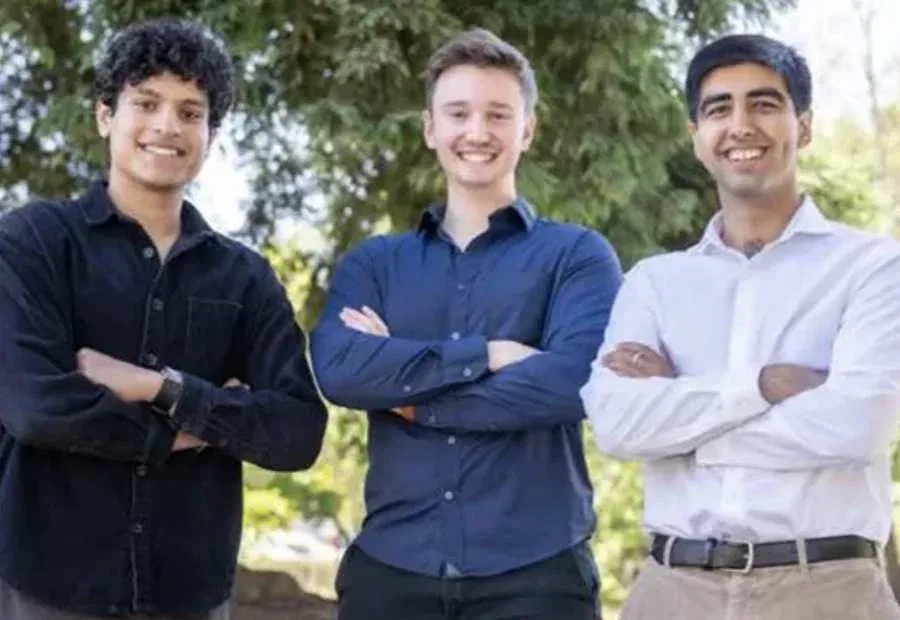
According to the company and investors, the round includes employee share sales. The funding will support model evaluation, post-training infrastructure and work environments for agents.
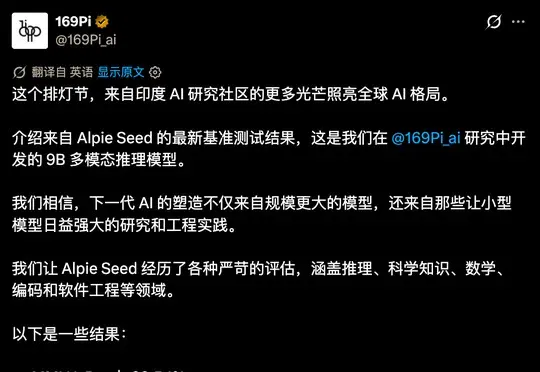
169Pi 发布的模型卡列出千问底座、量化和后训练方案。文章对比发布文案与模型资料,并讨论使用不同来源成绩做横向比较的限制。
闫俊杰在 Scottish Mortgage 播客解释低推理成本如何支持后训练,并讨论 H3 开放权重和 M3 Pro 的开发进度。访谈亦区分年化收入运行率与财报收入。
文章以 Fal 的 E、F 两轮融资为起点,分析统一模型 API、GPU 调度和后训练在生成式媒体中的作用,并讨论推理服务的单位成本、毛利和竞争格局。