An AI researcher's view of synthetic data, expert networks and outsourcing
Jinyan Su draws on post-training research and job-search experience to discuss data vendors' tasks, sales and quality checks. This is personal observation and commentary; anonymous examples are not independently verified or representative of every provider.
Editorial correction (November 19, 2026): This article presents personal observations. Absolute claims about platforms and data quality have been corrected, and unverified allegations naming individuals are not reproduced.
There is plenty of discussion about the AI data business, but most accounts come from data vendors or investors. The author, Jinyan Su, has a PhD in computer science from Cornell and works directly on post-training research. While looking for a job this year, she was also approached intensively by founders of data startups and recruiters.
From a position close to the data business without directly participating in it, Jinyan Su set out her observations in detail: what data vendors actually sell, where their data comes from, how they win orders and the gray areas behind the boom. As synthetic data becomes easier to generate and data quality remains hard to define, why does a business that appears to have low barriers to entry keep attracting entrepreneurs and capital?
This year, I looked for jobs mainly in post-training.
Almost all the startups that contacted me turned out to be data companies.
Even now, I still hear from numerous recruiters working on RL environments, founders of data startups and people hoping to move into the field who message me to request meetings.
I used to feel sad when people did not respond to my cold outreach. Now, with increasingly limited time and energy myself, I can no longer accommodate requests from strangers.
There is more and more noise online. Time and attention are becoming increasingly expensive, while sending someone a private message costs very little. With people I do not know well, saying no is often unavoidable. Even when I have met someone once, it is hard to judge what kind of person they are or whether spending my time will have any value.
Since many people are interested in this field, and the number has visibly grown over the past few months, I decided to collect my thoughts in a post.
01
Most people working on post-training
are dealing with data
In academic post-training, on a small scale, you can still tweak algorithms and enjoy yourself. I do not particularly care how general the resulting algorithm’s applications are or how large a model it can scale to, as long as I learn something and enjoy the process.
In industry, however, existing LLM training recipes, especially post-training, are already largely mature. Algorithmic innovation is becoming less common. Both the handful of open-source RL training frameworks and companies’ internal model-training frameworks are mature and stable. Improvements in models come almost entirely from data.
People working on pretraining clean data and study architectures, scaling and data mixtures. Those working on post-training mainly deal with various RL environments.
Of course, there is also mid-training: training on high-quality data to strengthen a model’s abilities in specialist domains.
Most people doing post-training in industry are also processing data. To make a model perform different tasks, we must train it on relevant data. The wider the range of tasks we want, the more diverse the required data becomes.
As for exactly what each so-called frontier lab in China or abroad buys—a complete RL environment, model-generated trajectories or complete data with chain of thought obtained through workarounds—and what they use it for, I do not know. My guess is that RL environments are used for RL training, while high-quality model-generated trajectories can provide an off-policy cold start through SFT before further on-policy distillation or RL.
02
Every data vendor claims to have know-how,
but the real advantage may simply be connections
Different vendors supply very different kinds of data. Many tiny, low-profile startups offer almost entirely synthetic data with a quick human review. Better-known startups in the field, such as Scale AI and Mercor, do recruit actual experts to label data.
Producing synthetic data costs almost nothing. That depends on the task, of course: tasks requiring GPUs can be costly. Browser and computer-use tasks only involve token costs, and most small data shops simply use personal accounts, making the cost almost negligible. Low costs and a lack of technical barriers make everyone want to try.
At a data-related event in Shenzhen in October, a newly graduated PhD was pitching enthusiastically to a group of people. He was literally beaming and gesticulating: his expression was so animated that every feature on his face, especially his eyebrows, seemed to dance. Once again I found myself marveling at the richness of Chinese: the four-character idiom mei fei se wu, literally “eyebrows flying, expression dancing,” can capture that whole scene so vividly.
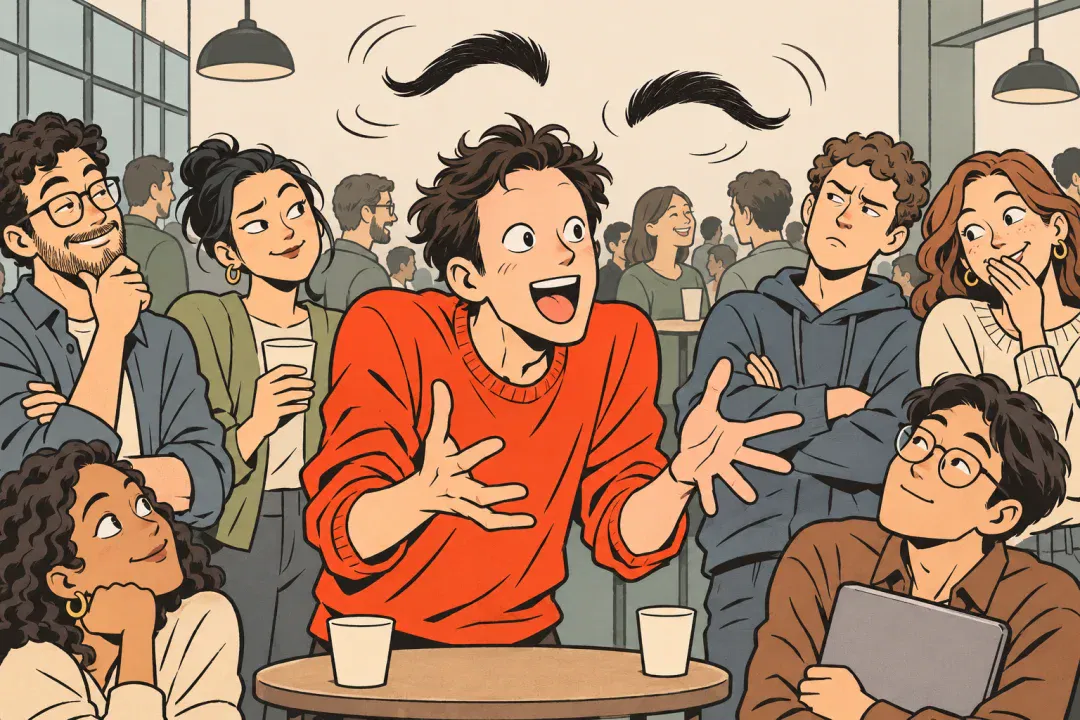
I asked him: with so many data companies around, what is your advantage?
He said: I am the only person at my company, so there is no extra overhead. I will do this for six months and see what happens.
I have asked many people that question. Most say, “We have better technology and have accumulated substantial know-how,” or “Frontier labs that use our data say we are better than other data vendors.” It seems every data startup has its own know-how, its own unique advantage and its customers’ approval.
It is like every paper claiming novelty and state-of-the-art results. When we first enter the field, we might look admiringly at whoever says this: after all, they possess mysterious technology that ordinary people like us could never imagine.
But after asking many companies, I still have not heard an idea that strikes me as refreshing.
Some startups also say they maintain strong networks of experts in specialist domains. What counts as an “expert” is unclear.
The answers I receive are all respectable-sounding pitches to impress investors. In my view, the only thing that can give a data startup a unique advantage is “connections”: knowing people at frontier labs or having worked in one yourself, understanding what they want and using those connections to sell them data. In China, I suspect that may also involve business meals, drinking and gift-giving.
Quality matters, but it is difficult for quality to become a barrier to entry. Enough startups can reach a certain quality threshold that it is hard to differentiate on quality alone.
“Quality” itself is also difficult to define, much like “expert” above. When model developers buy data, they generally inspect its “quality” visually or ask vendors to train a small model on it. There have also been cases where the same data improves one company’s model but performs poorly on another’s.
Often, details that you control rigorously and spend a great deal of time on may have no effect on the final outcome.
Research-oriented startups whose founders lack a distinctive advantage, unless very well funded, tend to face resource constraints. They end up building benchmarks and evaluations, producing data or assembling agent frameworks to make applications. These directions can also turn into one another: if an agent application fails, the company can switch to selling user data. If its evaluations and benchmarks attract attention from the industry and model developers, it can take the opportunity to sell data to those developers. Data vendors also build benchmarks in the hope that one will gain attention and bring them enough orders for a while.
03
Building benchmarks and giving away tokens
can both become data businesses
Here are some ways of selling data that I have observed:
1. Crowdsourcing task contributions
In academia, crowdsourcing tasks to build benchmarks is reasonable: resources really are limited. Some PhDs coming out of academia, drawing on extensive experience there, have expanded this crowdsourcing approach into their startups.
In academia, what people taking part in crowdsourced projects want is a place on the paper's author list; they actually do not care much about financial rewards. Also, because the work done by PhD students in academia is becoming less and less influential, people still hope for an opportunity like this to take part in projects that seem to have more impact. In addition, some Chinese students are more inclined to join such projects, because publishing papers can also help with their later green-card applications.
For example, one startup modeled its task crowdsourcing on Terminal-Bench and recruited participants on Xiaohongshu. I recently happened to read a Xiaohongshu post criticizing startups of this kind. Responses in the comments were mixed. The main criticisms were:
(1) Compared with Terminal-Bench, the tasks and process were unclear. Some people invested time but were ultimately not listed as paper authors.
(2) Promising paper authorship—in fact, they promised submission to ICLR and Nature—is effectively an empty promise: the paper may not be accepted.
(3) Their benchmark still has not been open-sourced. Academic crowdsourced research at least becomes open-source in the end, so people voluntarily contribute out of enthusiasm. Once those contributions serve a founder’s personal commercial interests, contributors should receive disclosure, reasonable explanations and compensation.
Note: these criticisms are not my own views. I am only recounting the content of the Xiaohongshu post.
2. Build a public benchmark, then sell data
Although I do not know marketing, many principles carry across fields. If there is no demand, create demand. If people are not anxious, create anxiety. Naturally, the benchmark has to make model performance look low; otherwise, who would buy their data?
From an academic perspective, if models perform too well on a benchmark, that suggests the problem being studied is not important. So model performance needs to be low there too.
Both academics and startups therefore have plenty of motivation to make model performance worse. A host of benchmarks strike me as unreasonable: either their verifiers are overly strict, so a model may solve the problem another way yet receive a low score; or the task itself is flawed, with ambiguities not explained to the model and several possible interpretations, yet an expectation that it follow one particular interpretation.
3. Build agent applications
Some agent-application companies, on the verge of closing, suddenly discover that someone will pay a high price for their data and switch on the spot to being data vendors. Others are operating well and, alongside their main business, generate synthetic data from user data to sell.
4. Free-token sites
They give you tokens to use, but take your data. When something appears free, you may want to think carefully about what you are unknowingly paying.
5. API relay services
The author discusses the risk that some third-party services may repurpose data from API calls without adequate disclosure. Services differ in their terms, implementations and behavior; this does not establish that all paid relay services sell data.
Payment alone does not prove that data will not be retained or repurposed. Any claim of improper handling still requires examining the specific service’s terms and evidence, rather than drawing a conclusion merely from the type of service.
I heard that one model developer bought data only to discover it was buying its own, because an API relay service it used had sold the data.
Besides earning money from selling data directly, there are other ways to profit, such as acting as an intermediary.
People who already have connections can contact buyers directly.
Many others lack connections, but through their determination, willingness to take risks and hardworking entrepreneurial spirit, they conduct outreach, seek introductions and gradually reach buyers.
Others may know little about the industry, have no connections or sales ability, and simply hold a batch of data. They have heard that data can be sold profitably but do not know how to sell it. Fortunately, it is relatively easy to find an intermediary willing to buy cheaply. They can let that intermediary take a margin, hand over the data and have it sold to a model developer.
04
As long as model developers can afford to buy and vendors dare to act,
the business keeps going
I previously posted on Twitter about my confusion over data sales. Why does the business remain so prosperous, with everyone apparently still making money, despite so many vendors entering and seemingly no barriers? Why are model developers’ in-house teams insufficient, making it necessary to spend so much on external procurement?
At first I thought the reason was expert data. If people must label it, surely it has to be sourced externally.
But much of the data is synthetic, and many small vendors lack relevant domain expertise and also produce synthetic data. As models become stronger, less data can genuinely be called “expert data”; manual labels by human experts may be worse than the model’s own output. Apart from vendors with truly top experts, do the others still have any value? For example, the Mistral Large 4 technical report says the environments, tasks, reference answers and verifiers used in post-training were mainly built or produced by agents themselves, without mentioning externally purchased data or human labeling.
As I said, generating synthetic data has no barrier to entry. It may once have required a sufficiently capable researcher, but now, with LLMs, even someone who does not understand research or have industry experience can learn how to do it with an LLM’s help. Some model developers with limited funds therefore do it themselves.
Budgets, compute and data-procurement strategies may affect decisions to buy externally; this is the author’s speculation. Buying more data does not necessarily improve a model. Incorrect, duplicate, mismatched or contaminated data may reduce training effectiveness, so spending an entire budget is not evidence of quality.
Another consideration is that even if they want to buy more compute, it may not be easy to obtain. If data is easier to buy, why not buy more data instead?
There are also legal issues. As a gray-area industry, the data business includes much that is unlawful. Model developers may be unwilling to handle these matters themselves, while vendors can operate at the edges of the law as intermediaries that keep the buyers’ hands clean.
The data industry’s enormous profits also make people, including some outwardly respectable researchers, willing to use unscrupulous methods. Consider the earlier example of an agent-application company switching to data sales after its application business failed. After two cofounders separated, founder A had already copied the data before the split—“better safe than sorry,” perhaps. Later, considering data sales, A logged back into the server maintained by founder B several months after their separation, trying to “steal” more data. B discovered this, and data ownership was ultimately determined through legal proceedings.
Some founders have also hinted that employees at companies or data firms should steal data from inside. As a bystander trying to stay out of it, I have seen all kinds of outrageous behavior around me when people face temptation and profit.
The author argues that conflicts of interest in data commercialization deserve scrutiny. The original draft also included allegations of misconduct against specific individuals. This article does not have sufficient primary evidence to support them, so it does not reproduce the named allegations or treat anonymous stories as verified findings from an industry investigation.
Whether the “experts” labeling data or those entering the data business after spotting the opportunity, it is like a building on the verge of collapse: nobody wants the building to fall, yet everyone is hastening its collapse.
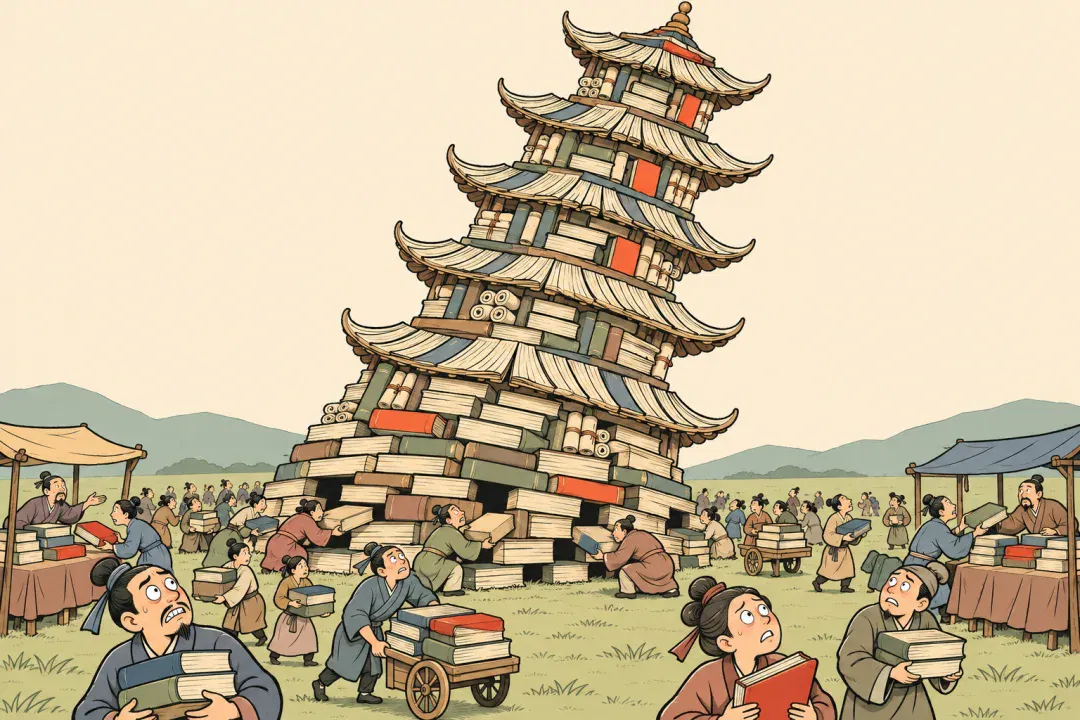
If you do not sell the data, someone else will. If you do not help label it, some other expert will. Whatever money you do not make, someone else will make—so why not earn it yourself? It is like everyone building more powerful models: nobody can stop. If one model developer stops while the others continue, will it not fall behind?
If labeling data as an expert, selling data against benchmarks as a vendor, and choosing whether to “steal” data are all optional, how much choice did employees have when a certain company forced them to record their screens and reassigned them to data labeling to improve its model?
This article was originally published by Founder Park. Author: Founder Park.
Related topics
After reading
Join the AINRK community
Read how to join the community and connect with people working in AI.
Related articles
Continue reading related topics and articles in this category.
大模型的数据生意:人类如何蒸馏自己 (opens in a new tab)
晚点走访数据生产者、供应商和模型团队,梳理专家怎样把工作任务、示范、操作轨迹和评分标准做成训练数据。文章也讨论采购独占、数据合规、自动扩写与标注劳动的报酬。
一个小数商的 AI 数据生意 (opens in a new tab)
报道以化名「小武」的经历串起训练数据转售、专家标注、企业数据交易与中转服务。文章结合多次访谈,部分细节经过模糊化,交易价格和规模来自受访者讲述。
LingBot robotics challenge ends: 48 hours on real robots test data and engineering (opens in a new tab)
Fifteen teams reached the LingBot challenge finals, tackling produce sorting, transparent-object storage and dual-arm work. TARS won with 82.50 points. The report highlights additional data collection, gravity compensation and on-site adaptation.
coScene raises nearly RMB 100 million in pre-A funding, focusing on real-robot data (opens in a new tab)
ChinaVenture interviews founder Yangming Huang on coScene's shift from infrastructure to data production, quality control, ecosystem partners and plans to collect data from deployed robots.
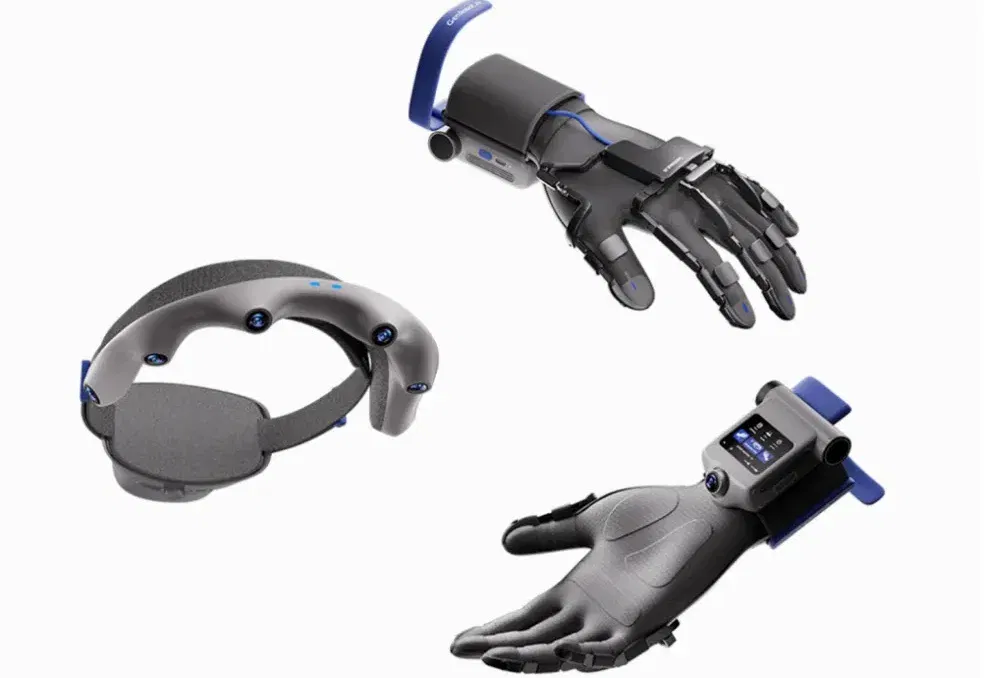
简智更新 Dex 与 Ego 采集设备,结合视觉、手部运动与触觉 (opens in a new tab)
简智介绍 Dex 2.0 数据手套与 DAS Ego 2.0 头戴设备,尝试将视觉、关节运动和触觉数据对齐。文中精度、重量等参数采用公司披露口径。