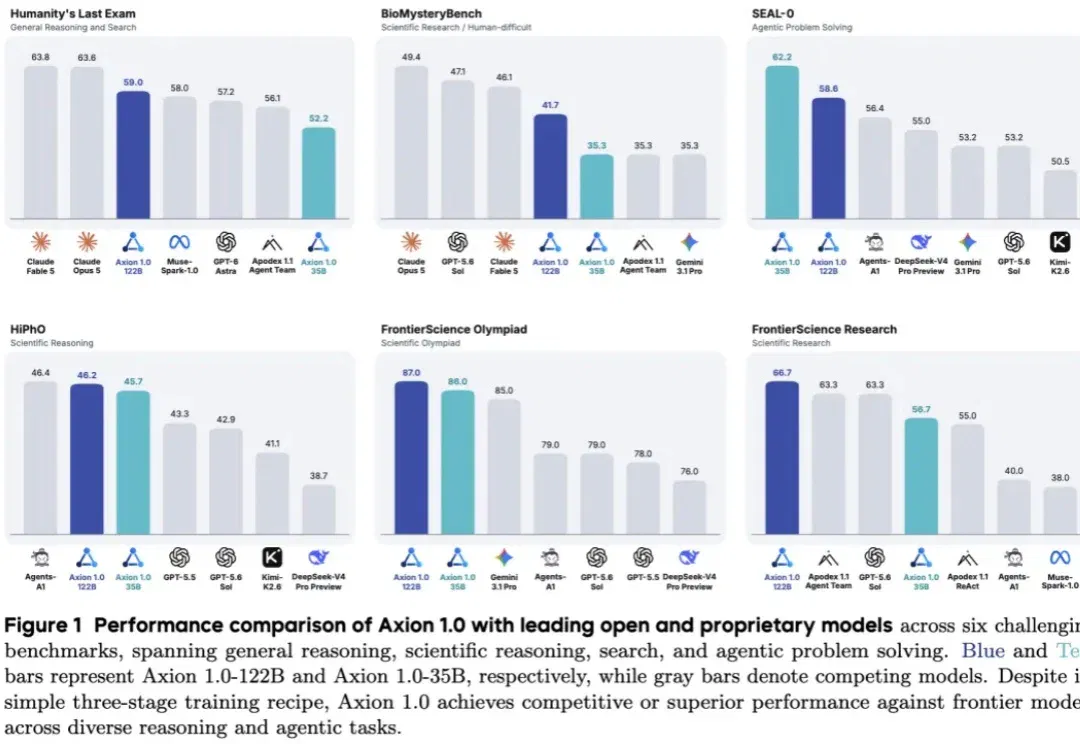
Axion 1.0 opens an agent-training pipeline using two-stage SFT and RL for scientific tool use (opens in a new tab)
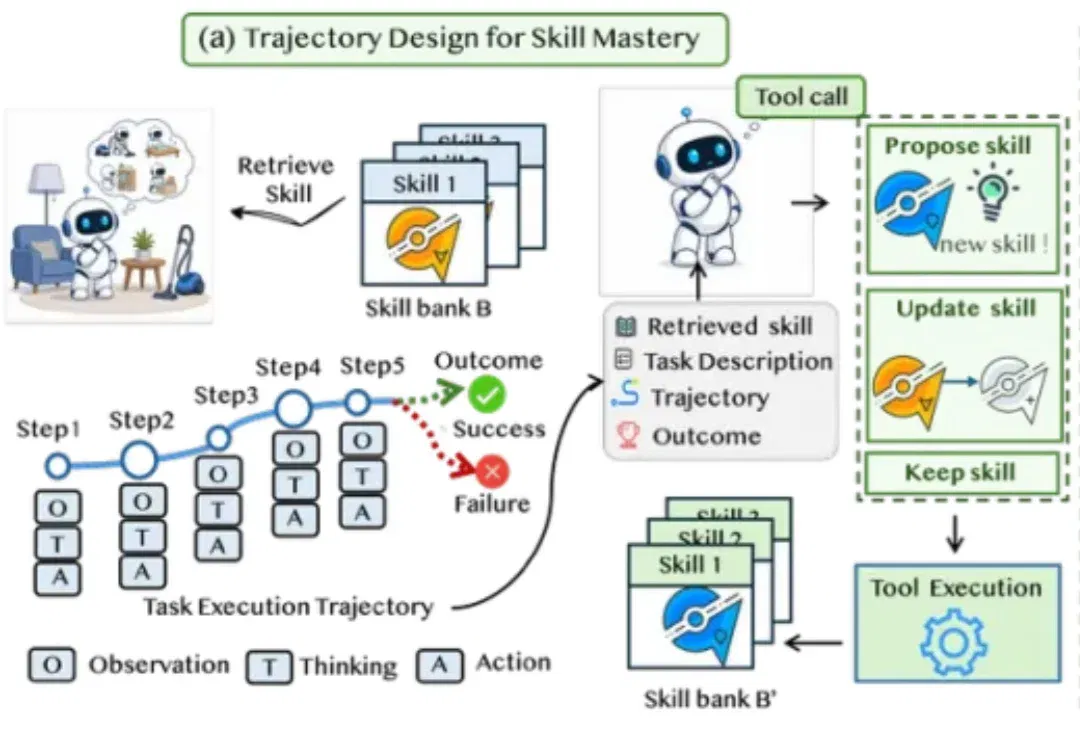
Researchers from Duke, ByteDance and other institutions present Axion 1.0, using supervised fine-tuning for reasoning and information acquisition followed by reinforcement learning. The paper reports mathematics, science and information-search results and releases training materials.