NVIDIA SEED cuts hybrid-model memory overhead; Qwen peak throughput per GPU rises up to 42% (opens in a new tab)
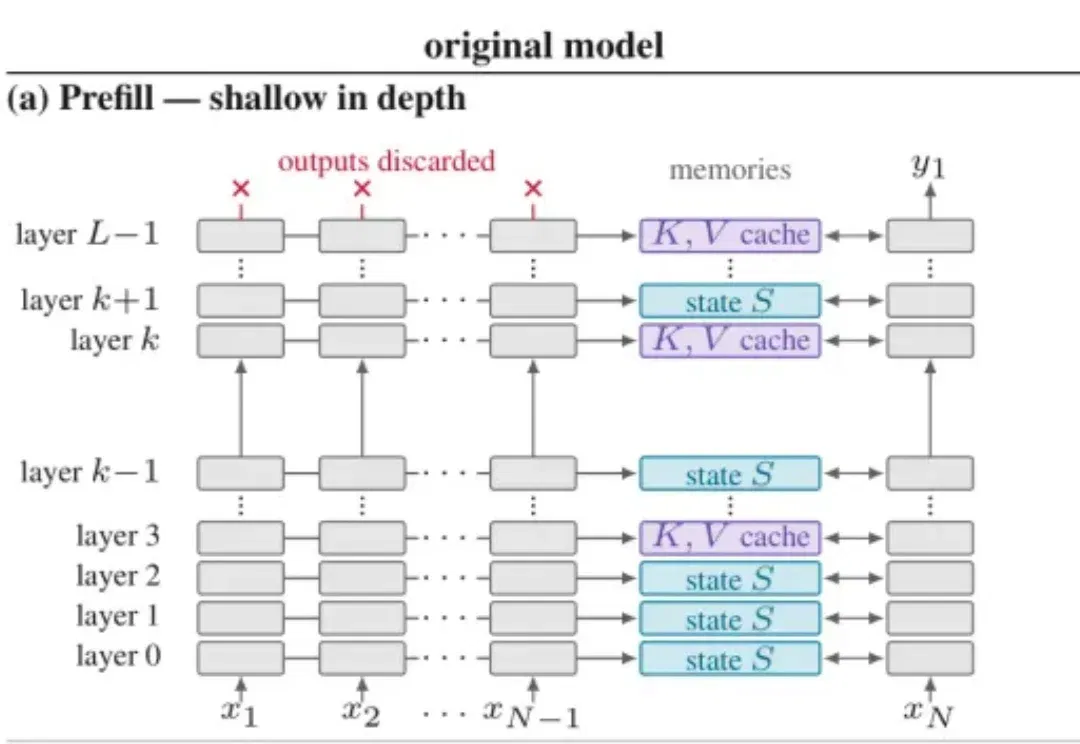
With original weights frozen, SEED reduces overhead using shallow prefill and low-rank recurrent states. Qwen3.8-Flash-Next tests on GB300 with SGLang and coding-agent sessions show 16%–42% higher peak throughput per GPU, counting input and output tokens rather than one user’s generation speed.