Shishi introduces multimodal inference services combining cache reuse and token compression (opens in a new tab)
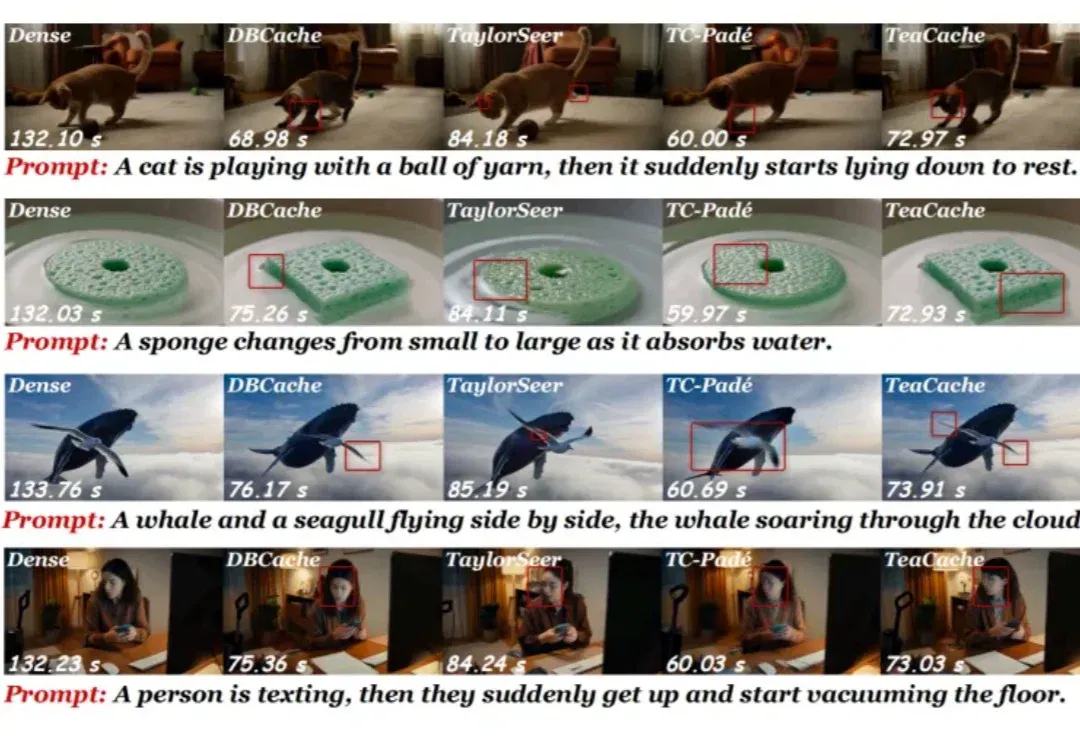
Shishi reports average 2.48-times video-inference acceleration over Dense in launch tests, alongside GPU-memory scheduling, asset understanding and structured context for generation. Results apply to the demonstrated settings.