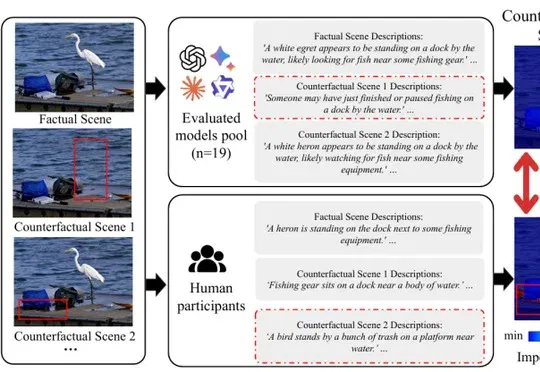
CSS scene-caption evaluation: Tested VLMs favor object size and are less sensitive to people (opens in a new tab)
UCSB researchers compare 19 VLMs with human descriptions across 307 original scenes and 1,306 object-removal variants. The tested models rely more on visual attributes such as size; size bias correlates with the accuracy gap.