Study Uses Astra to Edit 65 Token-Embedding Rows, Improving Robot Instruction Understanding
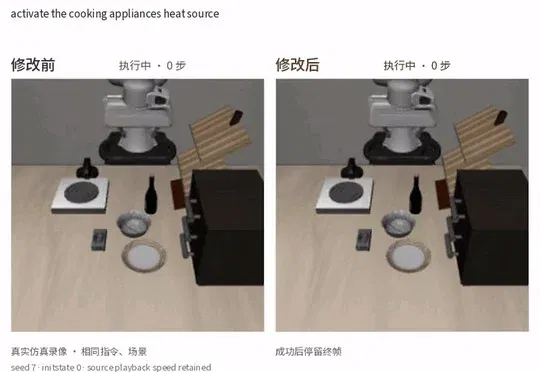
The best edit raised held-out simulation success from 86.3% to 92.0% across 765 episodes, with four regressions. Real-robot transfer remains unverified.
For 335 held-out instructions containing edited tokens, the success rate rose from 74.3% to 87.5%. For the other 430 episodes, each individual success or failure outcome was unchanged.
By changing just 65 rows of token embeddings, GPT-6 Astra repaired a class of robot failures triggered by rephrasing an instruction.
The task was to turn on the stove. The researchers' instruction to the robot was 'activate the cooking appliances heat source'—in other words, turn on the cooking equipment's heat source. The original policy instead reached for a plate and still had not completed the task after 300 steps.
With the edited weights, the robot completed the task at step 78 in the same scene, with the same instruction and random seed. The editing process used no gradient updates and added no new robot demonstration data.
Animation 1 | Robot behavior before and after editing for the same held-out instruction. The original policy on the left times out at 300 steps; the edited policy on the right succeeds at step 78, then holds on the final frame. The scene, random seed 7 and initial state 0 are identical, and the frames come from actual simulation recordings. This is a selected repair example; the full statistics also include episodes that regressed.
The research was conducted jointly by Jusheng Zhang, Keze Wang and Liang Lin, in a paper titled Can LLMs Debug Robots by Editing Their Weights? In the best-performing experiment, success on 335 held-out instructions containing edited tokens rose from 74.3% to 87.5%, while the success or failure outcome of each of the other 430 episodes was unchanged. 'Zero change' here refers to each episode's success or failure outcome.
The paper, weight edits that were actually evaluated, code and records of all 16 experiments are public. The research asks a specific question: can local weight edits make a robot's existing manipulation abilities more reliably accessible through different language expressions?
- Paper: https://arxiv.org/abs/2611.09376
- GitHub: https://github.com/jushengzhang/robot-weight-debugging
- Project introduction and process replays: https://jushengzhang.github.io/posts/robot-weight-debugging/zh.html
Put the LLM in the debugger's seat
The study uses the π₀.₅ LIBERO checkpoint released by OpenPI. It is a vision-language-action model that receives camera images, language instructions and robot state, then outputs the next actions to execute. The base model was already pretrained and fine-tuned. These edits were tested using LIBERO manipulation tasks and LIBERO-Plus instruction rewrites.[1][5][6]
In this experiment setup, Astra inspects and modifies the policy's weights. The researchers provide a persistent Python workspace and callable forward-pass tools. Astra can inspect tensors, write replacement values, and then check simulation-task results, actions or internal signals. Once an edit is fixed, the actions are still computed by the edited robot policy.
Each language edit has a budget of 50 counted tool requests, and one request can contain multiple episodes or inputs. Astra selects candidates using feedback from practice samples; results from the final held-out tests are not returned to it. Thus, 'No gradient updates' does not mean 'no feedback', still less that the robot had never been trained.
This shifts the question from whether the robot has learned the action to how the instruction is represented in the model, and whether that representation can call up an existing behavior more reliably.
Animation 2 | Replay of the actual process of GPT-6 Astra debugging robot weights. The researchers released key points from the 50 tool requests, showing how Astra adjusted token embeddings using simulation feedback, checked candidates and ultimately retained edits to 65 rows. On the left is robot behavior before and after editing for the same instruction; the bottom shows practice-sample results and tool feedback.
65 rows, where language enters the model
When an instruction enters the model, it is first split into tokens. A token does not necessarily correspond to a whole English word. The model then uses token IDs to retrieve the corresponding row vectors from the embedding table, and the subsequent network processes these numerical representations.
The edits Astra ultimately retained are concentrated in this embedding table. It selects some tokens and moves their vectors toward more common task expressions, such as cooker→stove, basin→bowl and fermented→wine. Some rows use the target vector, while others retain part of the original vector; ambiguous cases can also use the mean of multiple target vectors.
The word cooking in the opening stove instruction is a concrete example. Its token embedding was changed to 25% of the original vector plus 75% of the stove vector. The text given to the robot still contains cooking, but the numerical representation entering the subsequent network changes. This row is part of the complete 65-row edit; the study did not evaluate its effect separately.
Other examples also retain inspectable correspondences. In the wine-bottle instruction, fermented and grapes were moved toward wine. In the bowl-retrieval instruction, rounded was moved toward bowl, and uppermost toward top. The full token mapping and paired videos are public.
The 65 rows change 132,768 parameter values, or 0.00367% of the exported checkpoint. 'Rows' here means rows in the embedding table, not 65 parameters or 65 lines of code. The submitted language repair changes only these embedding values; the specific token IDs, target rows and mixing ratios are public.
Earlier research had already explored letting general-purpose LLMs directly read and rewrite neural-network weights, known as Weight-Space Programming.[2] ROME, MEMIT and MEND also study model editing.[8][9][10] This study examines the feasibility of LLMs constructing edits to robot policies through weight inspection and simulation feedback. It does not directly compare against those editing algorithms.
765 held-out instructions: 48 repairs, 4 regressions
One successful video cannot establish whether an edit is reliable. The study starts three separate editing searches from the same original checkpoint, without inheriting notes or modifications from one search to another. Once candidates are chosen, they are compared in pairs with the original policy on the same 765 held-out rewritten instructions.
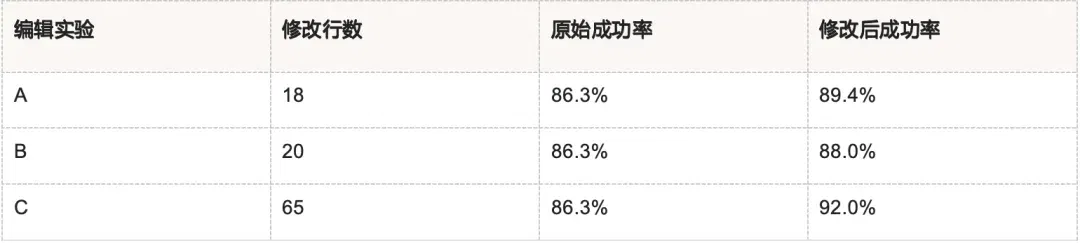
Table 1 | Held-out results from three independent editing searches. The tests use the same 765 instructions and random seed 7. The three primary tests remain significant after Holm correction for multiple comparisons. All three searches share the same test set and cannot be treated as three independent sets of test data.
The best edit, C, raised successes from 660 to 704. It made 48 previously failed episodes succeed, while four previously successful episodes failed, for a net gain of 44 successes. Overall success rose from 86.3% to 92.0%, an increase of 5.8 percentage points, with p=1.31×10⁻¹⁰ in an exact paired test.
Dividing instructions by whether they read edited embedding rows makes the location of the changes clearer. Among 335 episodes containing edited tokens, successes rose from 249 to 293, corresponding to 74.3%→87.5%. In the 430 episodes without these tokens, every individual success or failure outcome was unchanged.
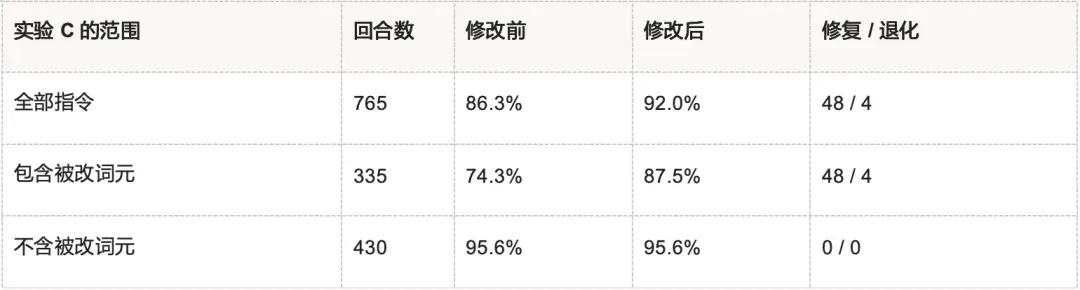
Table 2 | Edit C grouped by token coverage. The complete results count both repairs and regressions. 'Zero change' in the 430 episodes refers only to each episode's success or failure outcome.
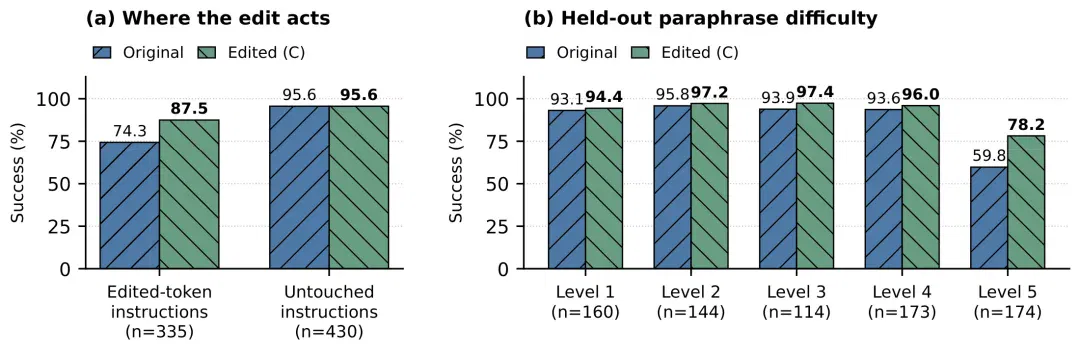
Figure 2 | Outcome changes from edit C are concentrated in instructions containing edited tokens. Success on the hardest rewrite level rose from 59.8% to 78.2%. The numbers in the figure come from per-episode records.
There is a direct explanation for this locality: if an instruction does not read any edited row, the text vectors retrieved by lookup are identical. When inputs such as camera observations and sampling noise are fixed, the rest of the unchanged network also receives identical computational inputs. Other new contexts containing these tokens may still be affected, however, so this does not guarantee the absence of side effects on every task.
From the stove to bowls and wine bottles: where do the repairs occur?
In the bowl-retrieval task, the instruction describes the target and location as 'darkcolored rounded container' and 'uppermost storage compartment'. The edited tokens rounded and uppermost were moved toward the embeddings for bowl and top respectively. In the same scene, the original policy timed out at 220 steps, while the edited policy succeeded at step 138.
Animation 3 | Bowl retrieval: the original policy times out at 220 steps; after editing, it succeeds at step 138.
The wine-bottle task describes the target as a glass container holding 'fermented grapes'. The embeddings for fermented and grapes were moved toward wine; this instruction also involves the atop→top edit. The original policy timed out at 300 steps, while the edited policy succeeded at step 90. These effects come from the complete 65-row edit, without separate ablation evaluations for individual tokens.
Animation 4 | Wine bottle: the original policy times out at 300 steps; after editing, it succeeds at step 90.
These are repair examples selected from the held-out tests. They help explain which edits the model reads, but the overall conclusions still rest on the paired results for all 765 episodes, including the four regressions. Complete instructions, token mappings and per-episode results can be inspected in the public code repository.
After one high score, an edit still has to withstand the next batch of samples
The final 65-row edit also went through a stage of appearing successful before problems emerged. In one editing run, the original model first succeeded 49 times on 80 harder rewrites of target tasks. Astra proposed changes to the vocabulary representations, and an early candidate reached 69/80 on this diagnostic set.
On a different batch of samples, that candidate repaired eight failed episodes but also caused six previously successful episodes to regress. A high score on the old samples did not end the search. Astra continued adjusting ambiguous lexical mappings, forming a candidate involving 65 embedding rows, freezing the changes first and then validating them on reserved practice samples.
After retrying runtime errors with the same seed and deduplicating, successes on 460 practice samples rose from 412 to 429. Astra ultimately retained this edit. Which tokens to select, which target vectors to move toward and how far to move each row were all proposed and checked by Astra within the session.
These points show how candidates were filtered, but scores from different practice batches cannot be connected into a training curve. Practice improvements cannot replace the final evaluation on 765 held-out instructions either. The complete trial-and-error process can be replayed attempt by attempt in the public experiment records.
Would simply swapping in synonyms do it?
A natural question is: do the gains come from Astra finding meaningful lexical correspondences, or could arbitrary small parameter perturbations improve results too? The study constructs two controls using the same 65 source rows.
The first moves in random directions, with movement distances matched to the original edits. The second keeps Astra's lexical correspondences but fully replaces each source embedding with its target embedding, retaining the use of means for multiple targets. This compares complete replacement of embedding values; the input strings are not rewritten.
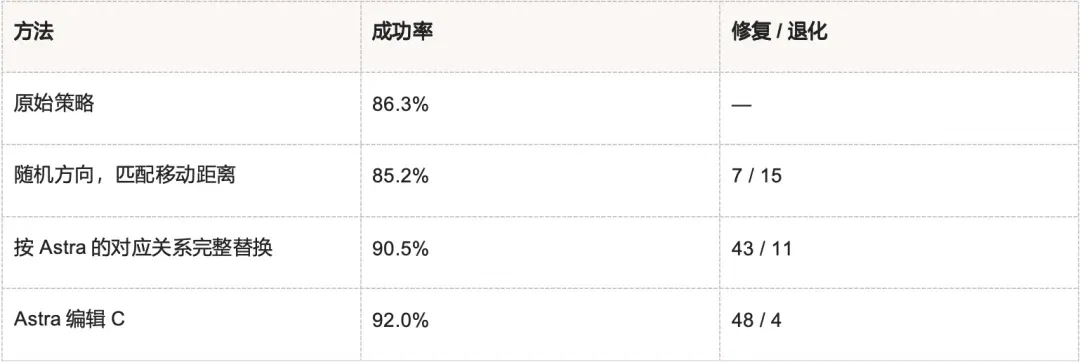
Table 3 | Controls on the same 765 episodes. Complete replacement has two runtime errors and the random control has three, counted as failures in the table. The paper also reports analyses excluding invalid pairs. The random directions are one control instance constructed for this study.
The random-direction control used here produced no improvement. Complete replacement already explained a substantial share of the gain, reaching a 90.5% success rate. This means that identifying which tokens need editing and where they should move is itself an important part of the repair.
Astra's edit C has a 92.0% success rate, a higher point estimate and fewer regressions. But its direct comparison with complete replacement on 763 valid pairs gives p=0.0614, which does not meet the 0.05 significance threshold. The current results therefore do not establish that partial mixing is significantly better than complete replacement, nor do they prove superiority over an independently compiled human lexicon, prompt rewriting or fine-tuning.
Failures to repair also leave a record
The 16 public robot experiments also cover camera viewpoints, backgrounds, language perturbations, instruction suffixes, LIBERO-RECOVER failure recovery and LIBERO-PRO robustness searches.[11][12] According to the paper's final decisions, all three language repairs were retained and had significant held-out gains. Of the other 13 searches, 12 abandoned their candidates. The only suffix follow-up counted as retained also had no significant held-out gain, with p=0.542.
The failure-recovery experiment illustrates the distinction well. One edit made the robot reopen its gripper more often after an empty grasp, but in one practice evaluation, actual task completions fell from 213/352 to 208/352. An internal signal changed as intended, but the task as a whole did not improve.
In reserved-practice validation for one recovery search, the final reserved-practice round had 288 valid pairs. Successes fell from 166 to 164, and the edit was ultimately withdrawn. The study did not use this to claim that it had repaired failure-recovery capability on the held-out set.
This makes retaining or withdrawing a candidate an outcome that needs checking just as much as proposing an edit. But 12/13 describes only the decisions in this set of runs; it is not enough to prove that LLMs generally know which failures they can repair. Historical runs also included finalization code that was not executed and withdrawn candidates left on disk. The framework bug has been fixed, and the materials distinguish archived files from final decisions.
A separate finding: numbers at the end of an instruction also change success rates
In FastWAM experiments, the study also found sensitivity to instruction format. Adding metadata such as 'view 0 0 100 2 354 initstate 0' to the end of a task description noticeably changed the policy's performance.[14]
On the same 210 paired episodes, FastWAM succeeded 70.0% of the time with plain task instructions, falling to 48.6% with the suffix. In comparison, the tested π₀.₅ had an overall success rate of 88.6% both times, but with nine improvements and nine regressions; individual episode outcomes were not all unchanged.
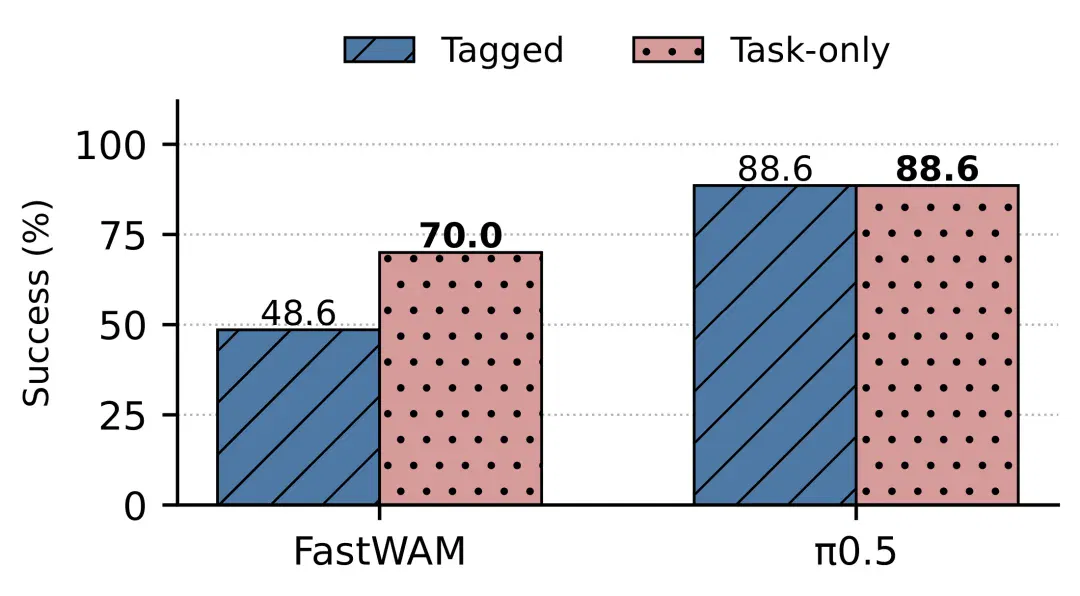
Figure 3 | Instruction-format sensitivity. Each checkpoint separately compares plain and suffixed task instructions on the same 210 episodes.
This finding has not become a stable weight repair. The first archived FastWAM candidate came with a withdrawal request, and subsequent experiments did not establish significant gains either. It therefore needs to be considered separately from the earlier π₀.₅ lexical repair: one is an observed evaluation phenomenon, while the other is an editing result supported by held-out evidence.
The comparison involves only two published checkpoints. World action models such as DreamZero and E0.5 provide a broader research context but are not part of this suffix test.[15][16] The question it leaves for evaluation is specific: when reporting success rates, exactly what complete instruction did the model receive?
Version one is open-source; real-robot validation is underway
The paper's title asks: can LLMs debug robots by editing their weights? These experiments give an affirmative result for one class of lexical-understanding failures: a small number of direct weight edits allowed a set of held-out instructions to call up manipulation behaviors already present in the policy more reliably. The complete causal path from language to action has not yet been localized layer by layer.
The validation scope also has clear boundaries. The main held-out test uses the same random seed. An early subset of 200 held-out instructions did not show a significant improvement; the same candidate was subsequently evaluated on the existing complete held-out split. Supplementary multiseed checks came from the practice set and showed uneven gains. All publicly released results are from simulation; transfer to real robots and the acquisition of new motor skills have not been validated.
The current open-source release is version one, v1. Version-two research and real-robot experiments are underway. GitHub provides the 65-row sparse edit that was actually evaluated and its application script, the execution framework, all 16 sessions and per-episode evidence. Readers can inspect the final scores and follow the records to see how candidates formed, which edits were abandoned, and the conditions under which the conclusions hold.
References
1. π₀.₅: a Vision-Language-Action Model with Open-World Generalization
2. Sparks of Weight-Space Programming: LLMs can natively read and write neural network weights
3. π₀: A Vision-Language-Action Flow Model for General Robot Control
4. OpenVLA: An Open-Source Vision-Language-Action Model
5. LIBERO: Benchmarking Knowledge Transfer for Lifelong Robot Learning
6. LIBERO-Plus: In-depth Robustness Analysis of Vision-Language-Action Models
7. Stable Language Guidance for Vision–Language–Action Models
8. Locating and Editing Factual Associations in GPT
9. Mass-Editing Memory in a Transformer
10. Fast Model Editing at Scale
11. LIBERO-RECOVER: Beyond Task Success Towards Failure Recovery in Robotic Manipulation Models
12. LIBERO-PRO: Towards Robust and Fair Evaluation of Vision-Language-Action Models Beyond Memorization
13. LoRA: Low-Rank Adaptation of Large Language Models
14. Fast-WAM: Do World Action Models Need Test-time Future Imagination?
15. World Action Models are Zero-shot Policies
16. E0.5: From Reconstructive to Future-Predictive 3D Foundations for Robotic World-Action Modeling
This article comes from the WeChat public account Synced and was written by Synced.
Related topics
After reading
Join the AINRK community
Read how to join the community and connect with people working in AI.
Related articles
Continue reading related topics and articles in this category.
Zhejiang University and Unitree open-source Movens-5M for multimodal whole-body motion pretraining (opens in a new tab)
Movens-5M pairs five million simulation-validated robot motions with text, video, speech and music. The team trains Movens-Zero and demonstrates it on a Unitree G1, using scaling experiments to examine gains from more data and larger motion experts.
Grid Robotics proposes an embodied-system framework separating models from closed-loop execution (opens in a new tab)
A Grid Robotics position paper proposes capability and responsibility levels around S0/S1/S2 roles, independent verification and time budgets. It examines the engineering needed to connect general-purpose models to physical systems; the framework is the team's proposal.
RoboRisk tests robotic semantic hazards; LEASH reduces harm within specified tasks (opens in a new tab)
RoboRisk evaluates model-controlled robots on 92 simulated and thirteen physical tasks, testing LEASH’s three gates. Some configurations incurred no harm in the physical sample; this does not guarantee safety in open environments.
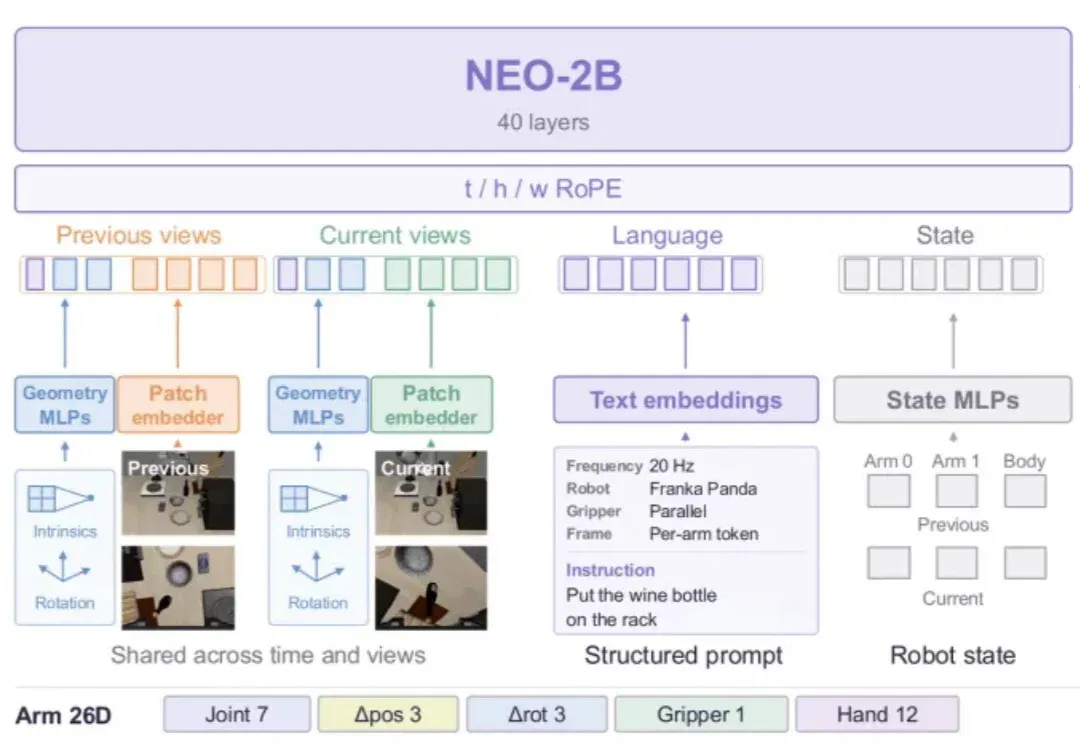
NEO-VLA studies how native visual representations support robot action learning (opens in a new tab)
NEO-VLA lets an action expert read multiple backbone layers, comparing frozen models, fine-tuning and joint understanding training. Simulation and three physical tasks evaluate transfer, robustness and remaining spatial/task-generalization limits.
RoboSpoof Tests How Visual Interference Affects Robots' Safety Refusals (opens in a new tab)
Robocurve compared original, blurred and AI-tampered images across 900 trials with five models and five tasks, reporting a sharp increase in dangerous-action attempts under controlled, prop-based conditions.