Claude Code 每条请求暗藏一行「有毒」header,52K 上下文推理被拖慢 5 倍!NVIDIA 一个 flag 修好了
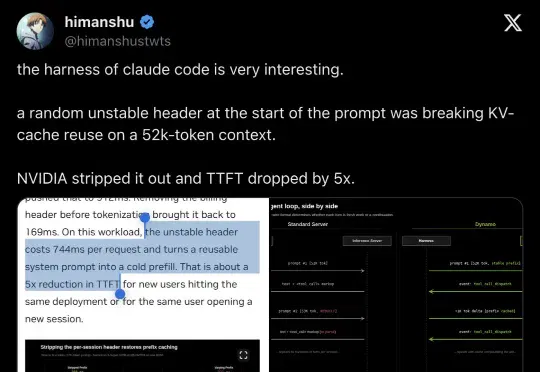
NVIDIA Dynamo 团队发现,Claude Code 向自定义端点发送请求时,prompt 最前面会带一行 session-specific billing header。这行 header 每个 session 都变,导致 52K token 的稳定前缀在 KV cache 中无法复用——TTFT 从 168ms 飙到 912ms。Dynamo 加了一个 `
导读
【导读】NVIDIA Dynamo 团队发现,Claude Code 向自定义端点发送请求时,prompt 最前面会带一行 session-specific billing header。这行 header 每个 session 都变,导致 52K token 的稳定前缀在 KV cache 中无法复用——TTFT 从 168ms 飙到 912ms。Dynamo 加了一个 `--strip-anthropic-preamble` flag,TTFT 立刻回到 169ms,快了将近 5 倍。
模型没换,GPU 没换,TTFT 差了 5 倍
同一个模型,同一块 B200,同一段 52K token 的 prompt。
NVIDIA Dynamo 的测试结果:
- KV cache 正常命中时,TTFT168ms
- 保留一行 session-specific billing header,TTFT912ms
- 用 `--strip-anthropic-preamble` 去掉 header,TTFT169ms
差异来自一行字。代价是744ms/请求。
开发者 himanshu 在 X 上分享了这个发现,原话是:
"a random unstable header at the start of the prompt was breaking KV-cache reuse on a 52k-token context. NVIDIA stripped it out and TTFT dropped by 5x."
「prompt 开头的一个不稳定 header 破坏了 52K 上下文的 KV-cache 复用。NVIDIA 把它去掉后,TTFT 降了 5 倍。」
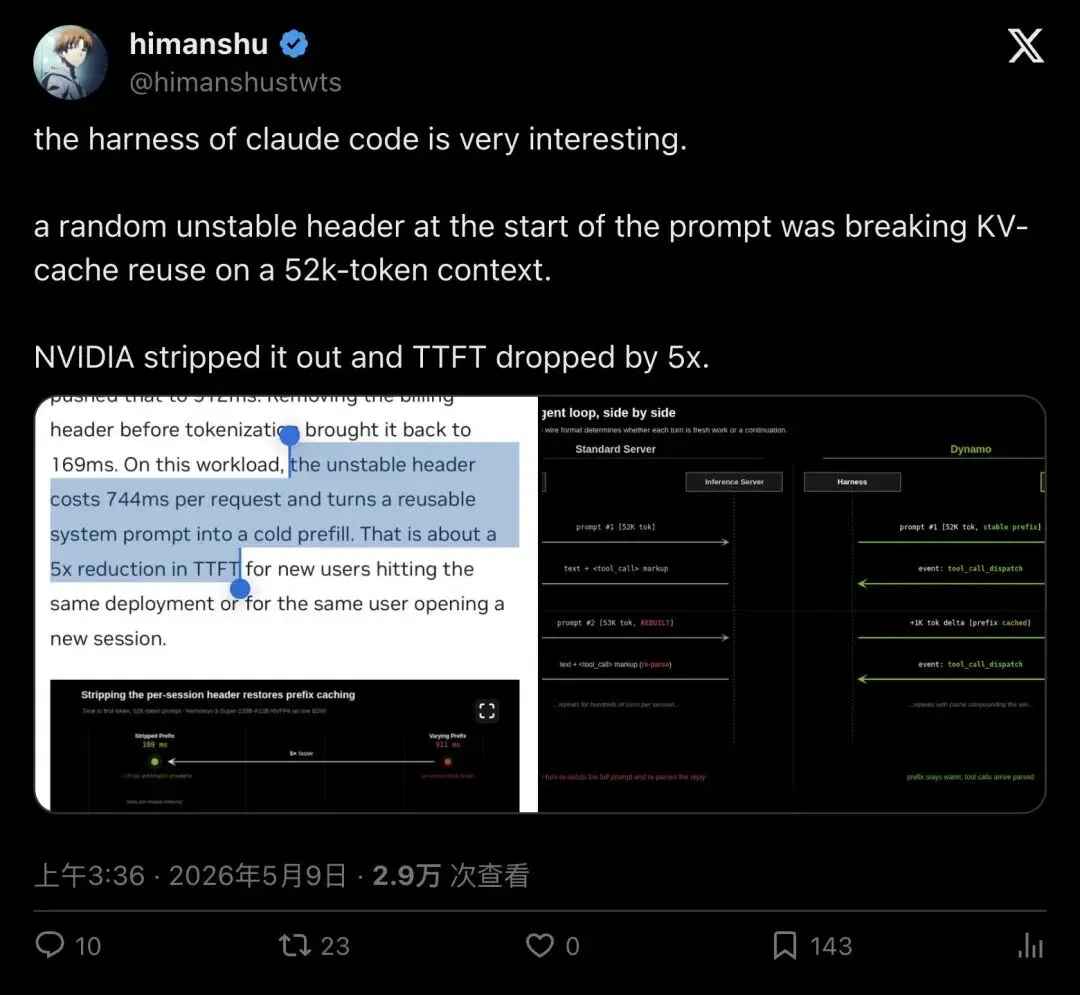
▲ himanshu 在 X 上分享 Claude Code KV-cache 问题,附 NVIDIA 文档截图
但要理解这 5 倍差距从哪来,得回到 NVIDIA 的官方文档。
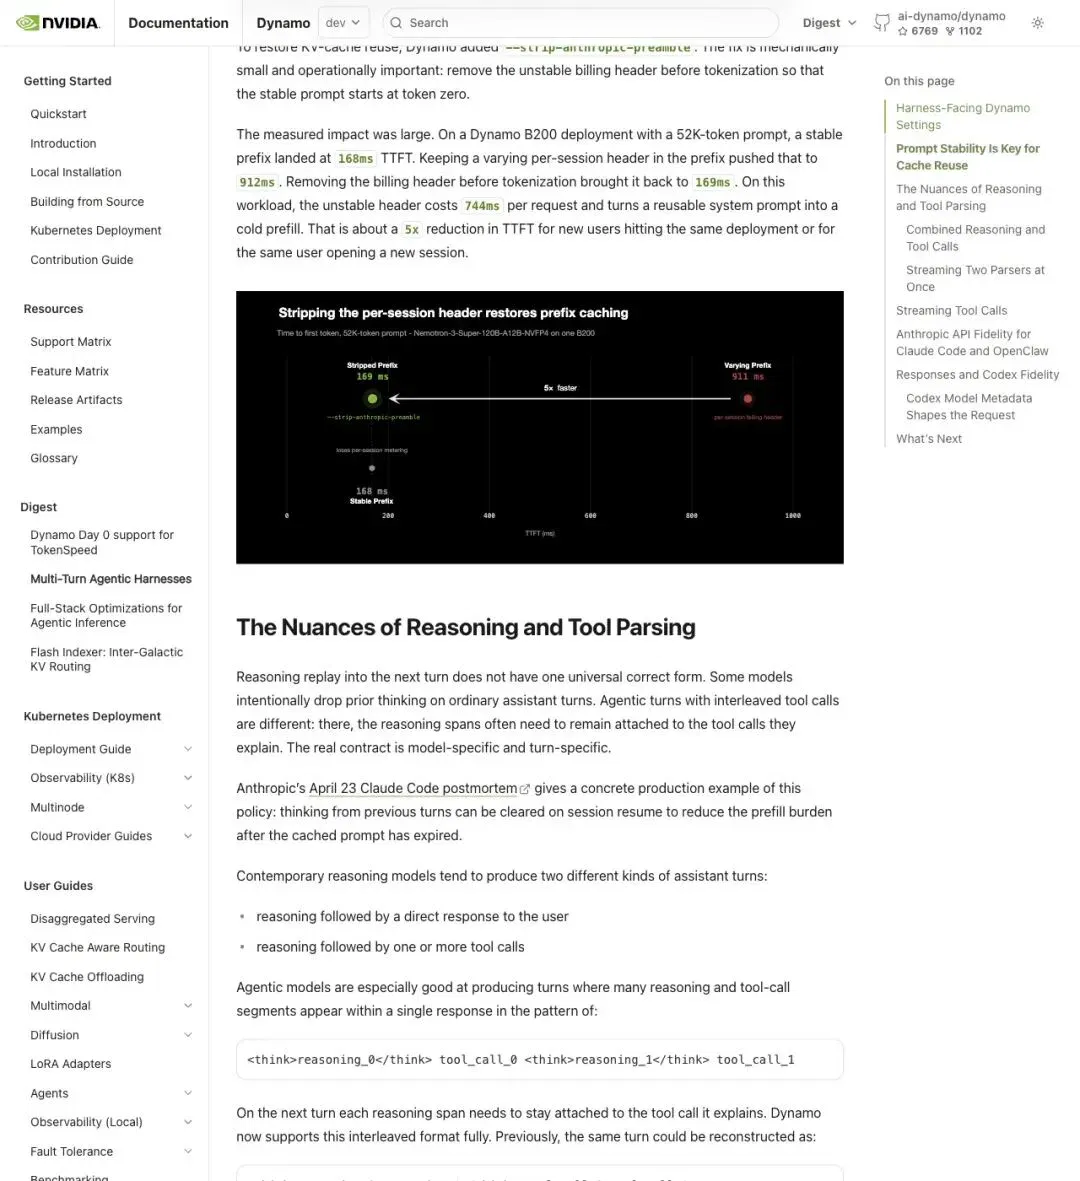
▲ NVIDIA 文档 TTFT 对比图:Stable Prefix 168ms、Varying Prefix 911ms、Stripped Prefix 169ms,标注 5x faster
这行 header 长什么样
NVIDIA Dynamo 文档给出了示例:
```text x-anthropic-billing-header: cc_version=0.2.93; cch=abc123def456==; You are Claude Code, an interactive CLI tool... ```
`x-anthropic-billing-header` 出现在 prompt 最前面,token 序列的第 0 位附近。每个 session 的值都不一样——版本号、billing 标识都在变。
关键在于:KV-cache 的 prefix 匹配从第一个 token 开始,逐 token 比对。
只要第 0 位的 token 变了,后面即使有 52K token 完全相同的 system prompt、tool definitions、对话历史,prefix cache 都不会命中。全部从头算。
NVIDIA 文档用了一个词:poison。
"These headers poison the KV cache and prevent it from being reused... A varying line at position zero means every new session starts from a different token prefix..."
「这些 header 会『污染』KV cache 并阻止复用……第 0 位的一行变化,意味着每个新 session 都从不同的 token prefix 开始。」
一次 cold prefill 就要把 52K token 全部重新计算。168ms 变成 912ms 就是这么来的。
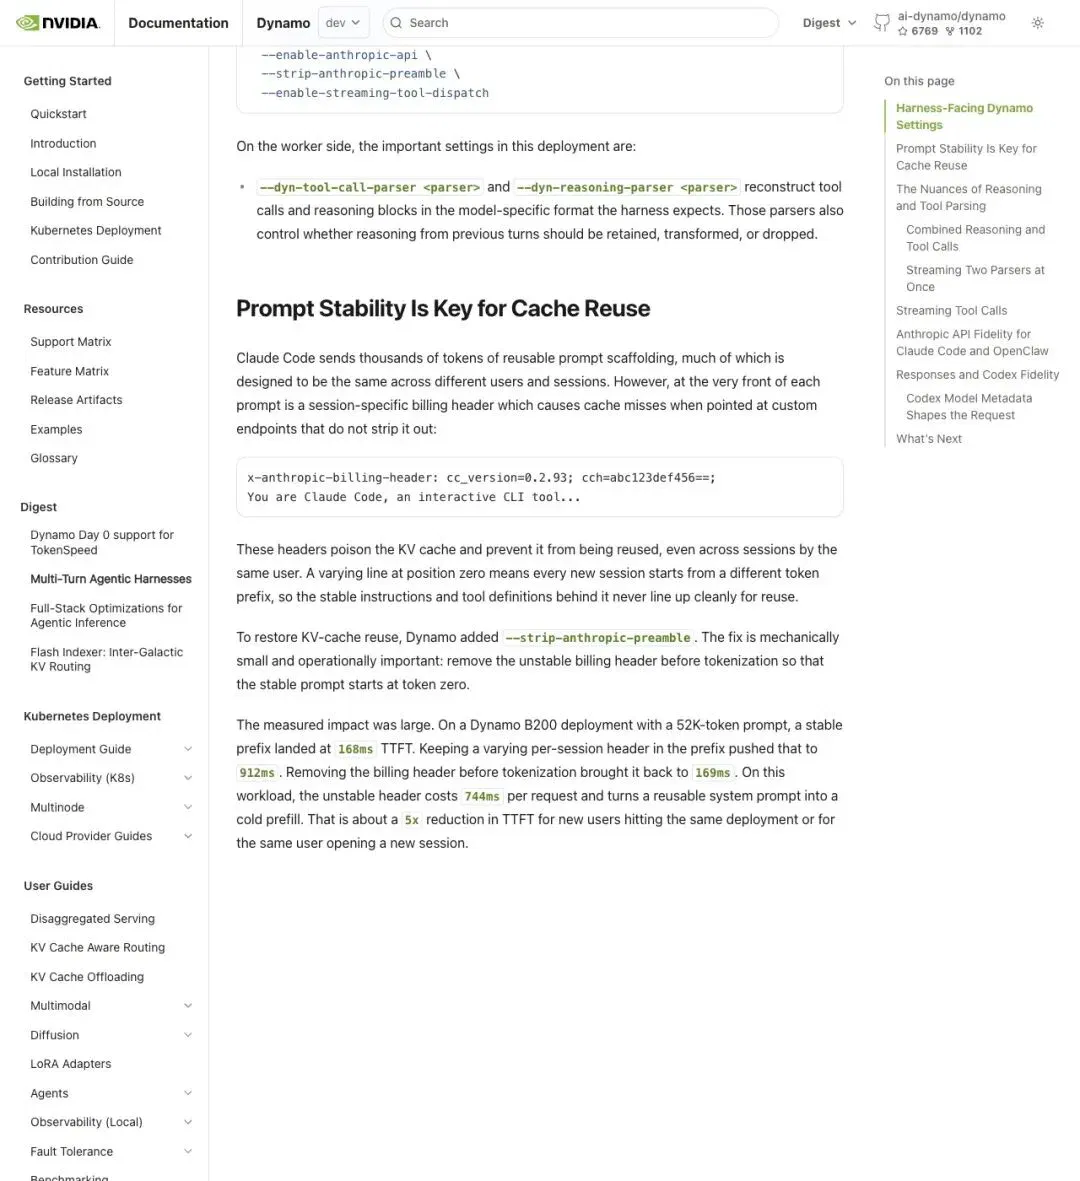
▲ NVIDIA Dynamo 文档 "Prompt Stability Is Key for Cache Reuse" 段落,含 billing header 示例和 KV-cache 失效机制
为什么 coding agent 对此特别敏感
普通聊天可能就几轮对话。Coding agent 完全不同。
NVIDIA Technical Blog 的描述:
"Tools like Claude Code and Codex make hundreds of API calls per coding session, each carrying the full conversation history."
「Claude Code 和 Codex 一次编码会话可能发起数百次 API call,每次都携带完整对话历史。」
数百次请求,每次都拖着不断增长的上下文。KV-cache 复用在这种场景下收益巨大:
- 首次 API call 写入 KV cache 后,后续请求在同一 worker 上可以命中85–97%cache
- 4 个 Opus teammates 的 agent swarm 可以达到97.2%aggregate cache hit rate
- 11.7x的 read/write ratio——系统写一次 cache,读近 12 次
典型的 write-once-read-many 模式。Cache 命中时效率极高,但只要 prefix 匹配失败,所有优势瞬间归零。
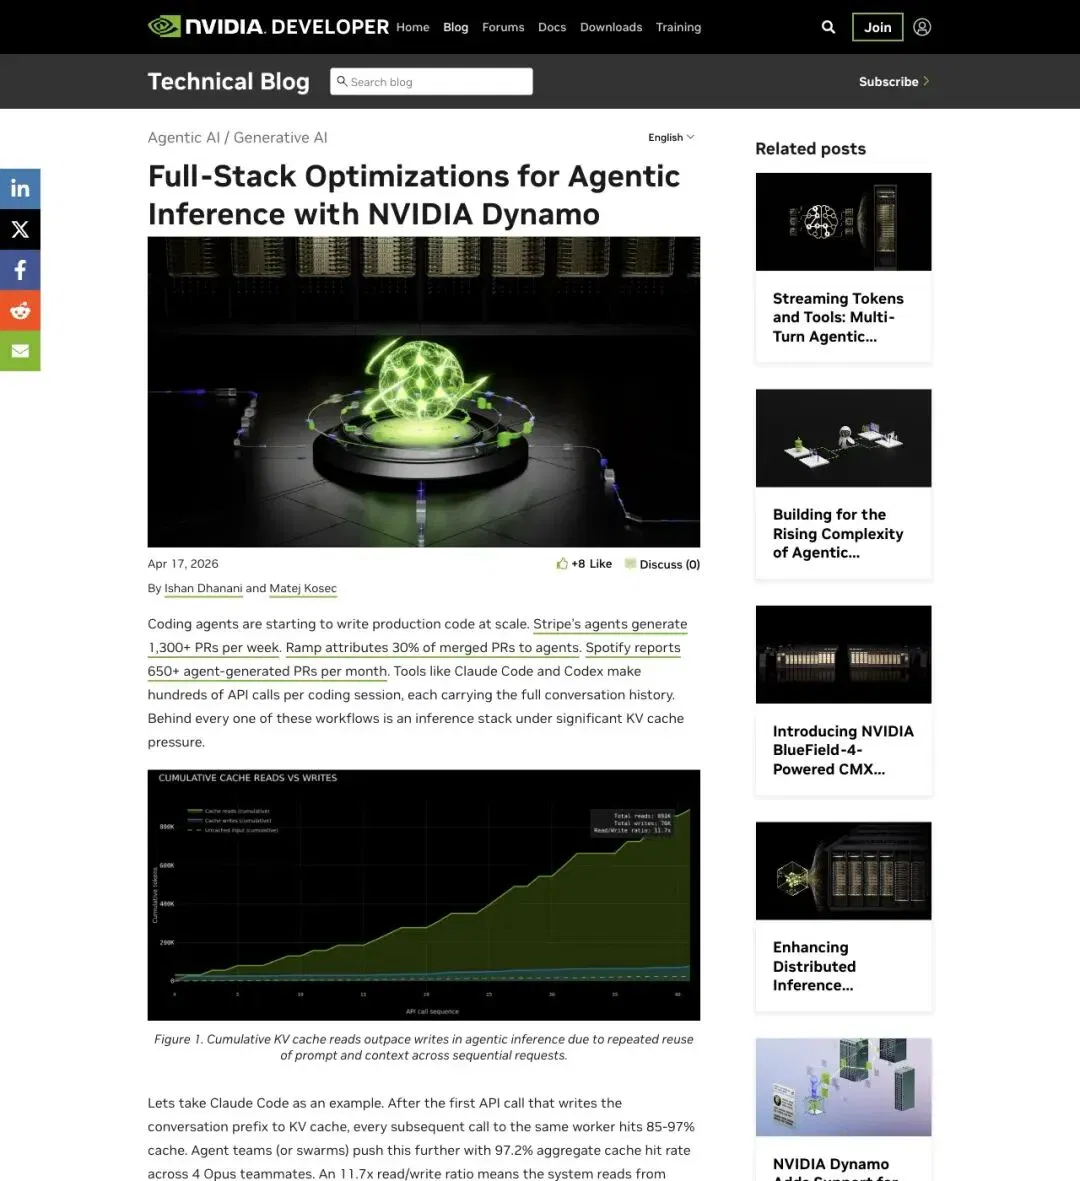
▲ NVIDIA Technical Blog:Full-Stack Optimizations for Agentic Inference with NVIDIA Dynamo
修复方案:在 tokenization 前把 header 剥掉
Dynamo 的方案就一步——在 tokenization 之前移除不稳定 header:
"remove the unstable billing header before tokenization so that the stable prompt starts at token zero."
「在 tokenization 前移除不稳定 billing header,让稳定 prompt 从 token zero 开始。」
具体操作是在 Dynamo 启动配置中加上 `--strip-anthropic-preamble`,和 `--enable-anthropic-api`、`--enable-streaming-tool-dispatch` 配合使用。
不改模型、不改 GPU 配置、不改 prompt 内容。只在请求进入 tokenizer 之前做一次字符串处理。TTFT 从 912ms 回到 169ms。
这算 bug 还是设计选择?
社区对此有不同看法。
X 上 @drummatick 的观点:
"technically it's not a harness issue"
他认为这个 billing header 可能是 Anthropic 有意放在每个请求里的。在 Anthropic 官方 API 端点上,它不会造成性能问题——Anthropic 自己的基础设施知道怎么处理它。
问题出在自定义 endpoint。当用户把 Claude Code 指向第三方推理服务(比如用 Dynamo 部署的本地模型),这行 header 就变成了 prompt 前缀里的"异物"。推理服务不认识它,也不知道要把它剥掉,KV cache 的 prefix 匹配就会失败。
简单说:Anthropic-compatible request path 转接到自定义 endpoint 时的兼容性缺口。Dynamo 在服务端加了 `--strip-anthropic-preamble` 来填补这个缺口。
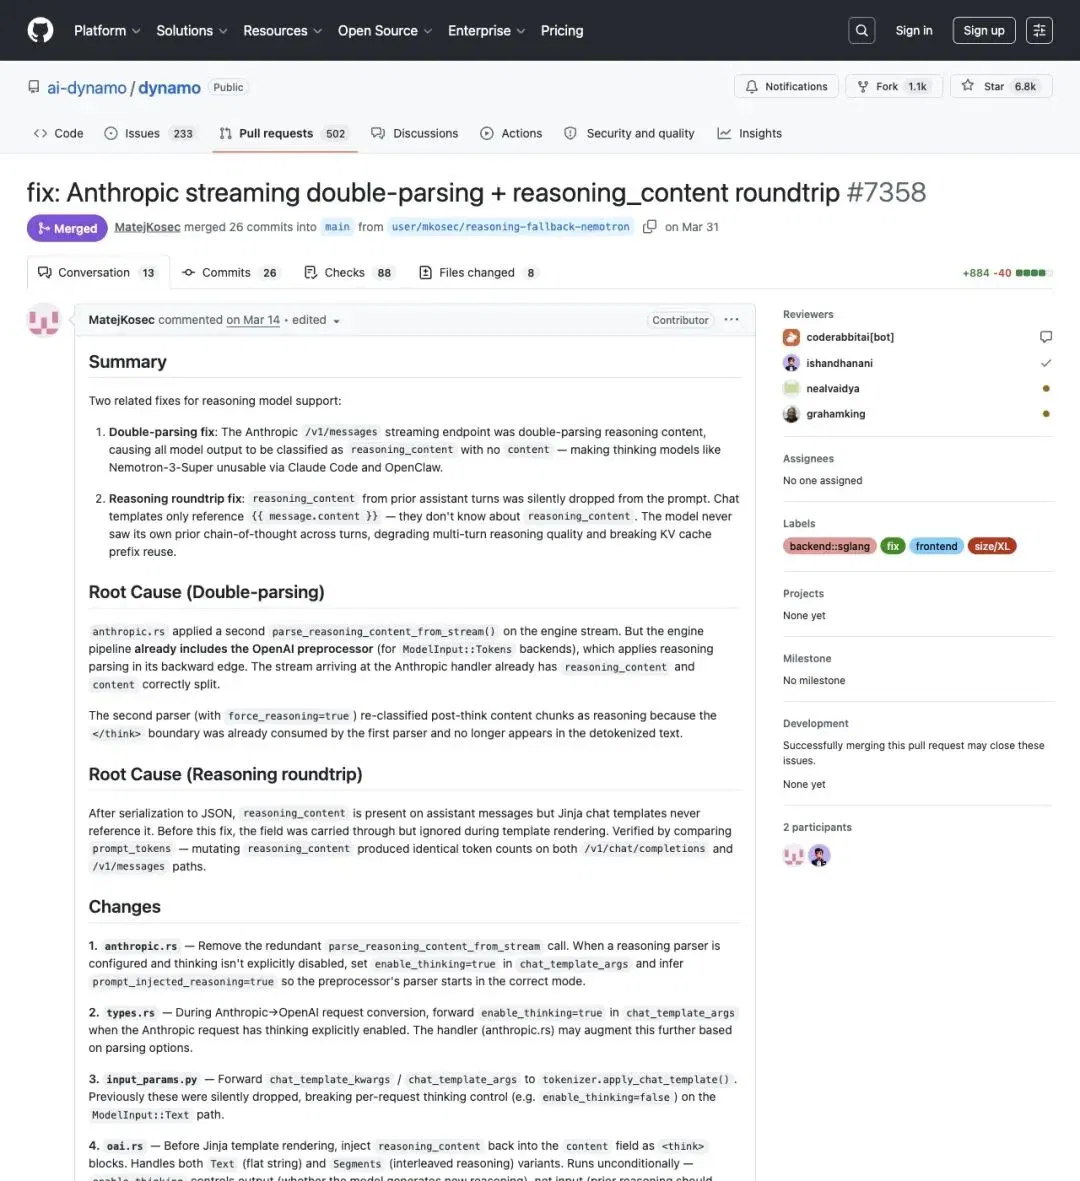
▲ GitHub ai-dynamo/dynamo PR #7358:Anthropic streaming 的 double-parsing 和 reasoning_content roundtrip 修复。Anthropic-compatible 的 agent harness 支持涉及大量这样的协议细节。
瓶颈经常藏在模型之外
这个案例值得所有做 agent serving 的团队注意:模型能力、GPU 算力一个没变,仅仅因为 prompt 开头多了一行动态字段,推理延迟就差了 5 倍。
NVIDIA 两篇 Dynamo 文档串起来看,长上下文 agent 的推理性能至少取决于三个层面:
第一,prompt prefix 稳定性。前缀 token 序列不能因为 billing header、随机 ID、timestamp 等动态字段而失配。
第二,cache locality 和 routing。后续请求要落到持有相关 KV blocks 的 worker 上,或者有机制做跨 worker 共享。
第三,协议和 parser 的准确性。Anthropic Messages API 的 reasoning blocks、tool_use blocks、streaming events 都需要正确解析和 roundtrip。PR #7358 修的就是 streaming double-parsing 和 reasoning_content roundtrip 问题。
当 coding agent 一次会话发起数百次 API call、每次携带 50K+ token 上下文时,这些工程细节的影响会被放大到用户直接可感知的程度。
一行 header,744ms/请求,乘以数百次调用。这才是 agent 推理的真实成本结构。
文章来自于微信公众号 "桂宫说事",作者 "桂宫说事"
Related topics
After reading
Join the AINRK community
Read how to join the community and connect with people working in AI.
Related articles
Continue reading related topics and articles in this category.
Claude Code desktop opens theme mods for colors and animated customization (opens in a new tab)
The article describes natural-language creation of visual mods and official theme examples, alongside comparisons with other coding tools. Support varies by version and plugin; appearance and comfort differ across people and devices.
Claude Code 用户报告账号邮箱被写入外部请求 (opens in a new tab)
用户在公开工单中提供了请求头和上下文案例。Anthropic 的发布记录提到为含账号邮箱的网络调用加入检查,报道也梳理了脚本调用的边界。
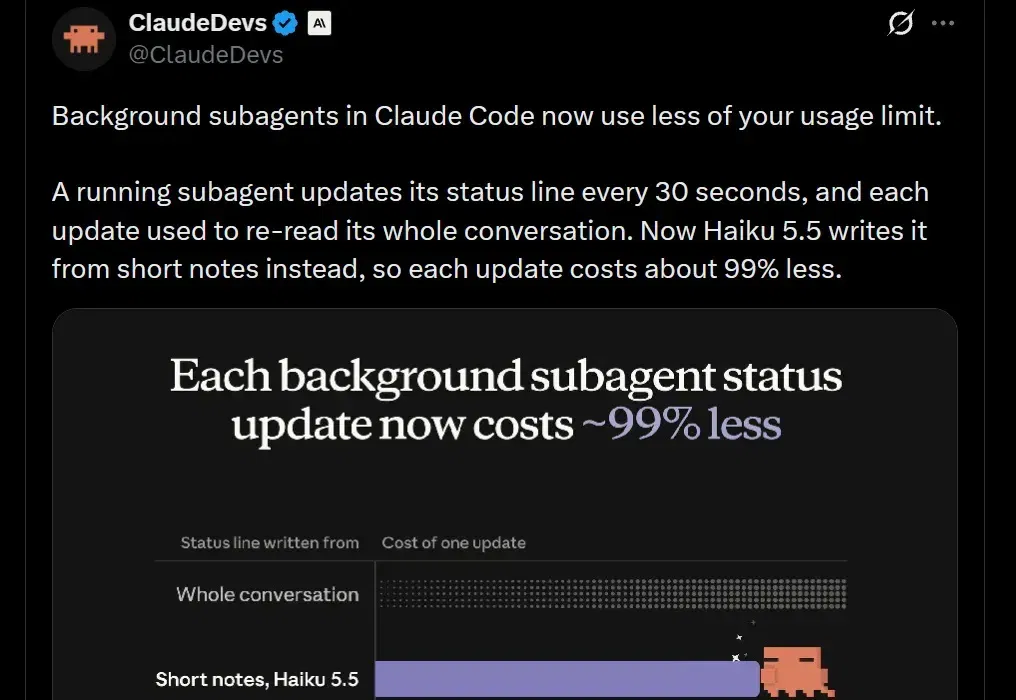
Claude Code 调整子代理状态行,单次更新成本约降 99% (opens in a new tab)
据 Claude Code 团队介绍,CLI 后台子代理的状态更新改由 Haiku 读取短笔记。单次状态行成本约降 99%,带后台子代理的整段会话额度消耗约降 5%。
前 Claude Code 产品负责人 Cat Wu 宣布加入 OpenAI (opens in a new tab)
据报道,Cat Wu离开Anthropic后宣布加入OpenAI,参与核心产品管理。文章回顾她在Claude Code及Cowork的工作,并讨论团队人员流动;Anthropic公司收入增长不能全部归于单一产品,也不能从离职直接推断内部矛盾。
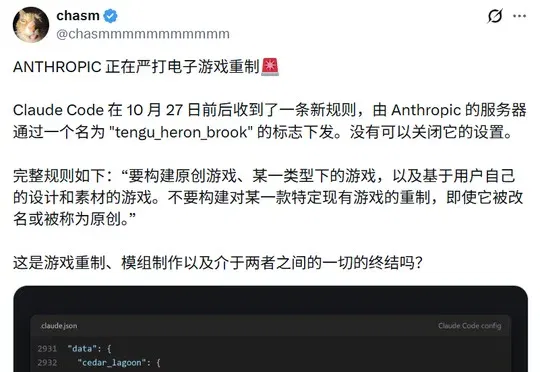
Claude Code 调整游戏生成提示:允许原创,限制复刻特定作品 (opens in a new tab)
据报道,Anthropic 为 Claude Code 使用 Opus 5.5 时加入提示,允许原创、类型游戏及用户自有设计,限制复刻某款现有游戏。开发者 Addy Osmani 表示团队仍会调整边界并收集误拒反馈;文章进一步讨论 Mod、游戏保存与克隆风险,实际执行仍取决于模型理解。