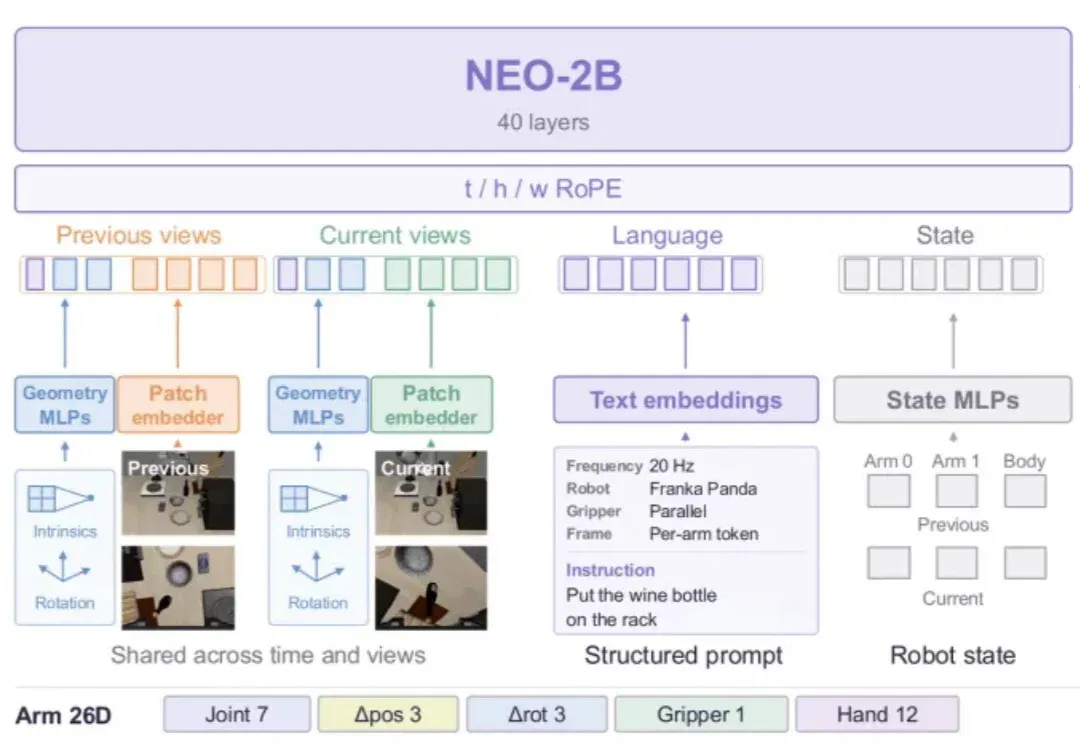
NEO-VLA studies how native visual representations support robot action learning (opens in a new tab)
NEO-VLA lets an action expert read multiple backbone layers, comparing frozen models, fine-tuning and joint understanding training. Simulation and three physical tasks evaluate transfer, robustness and remaining spatial/task-generalization limits.