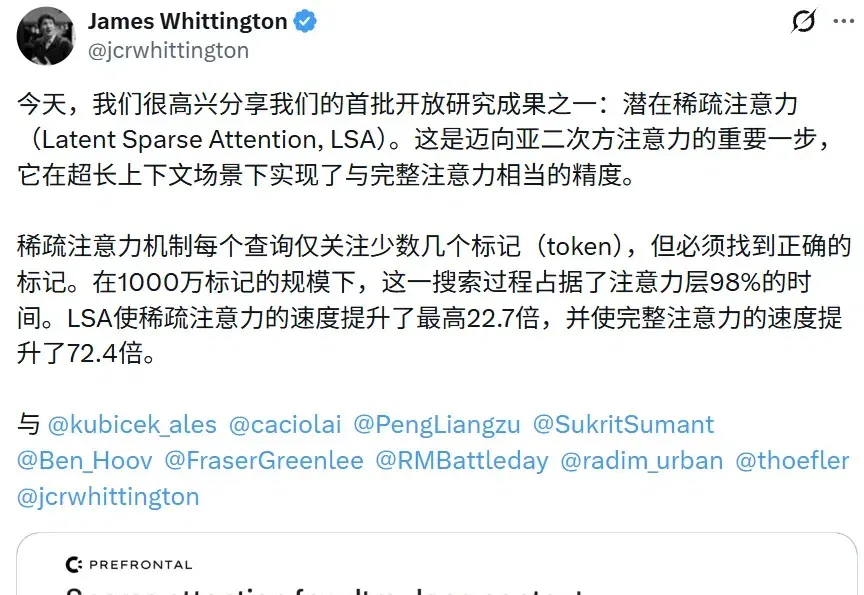
LSA speeds up single-layer prefill 22.7-fold in a ten-million-token context test (opens in a new tab)
Prefrontal AI and ETH Zurich propose Latent Sparse Attention, using clustering and hierarchical indexing to select past tokens. The paper separates single-layer computation from whole-model time to first token; 22.7x refers to a specified GLM attention-layer test.