教程:如何用Hermes+Milvus,搭建GEO Pipeline,提升产品的AI引用率
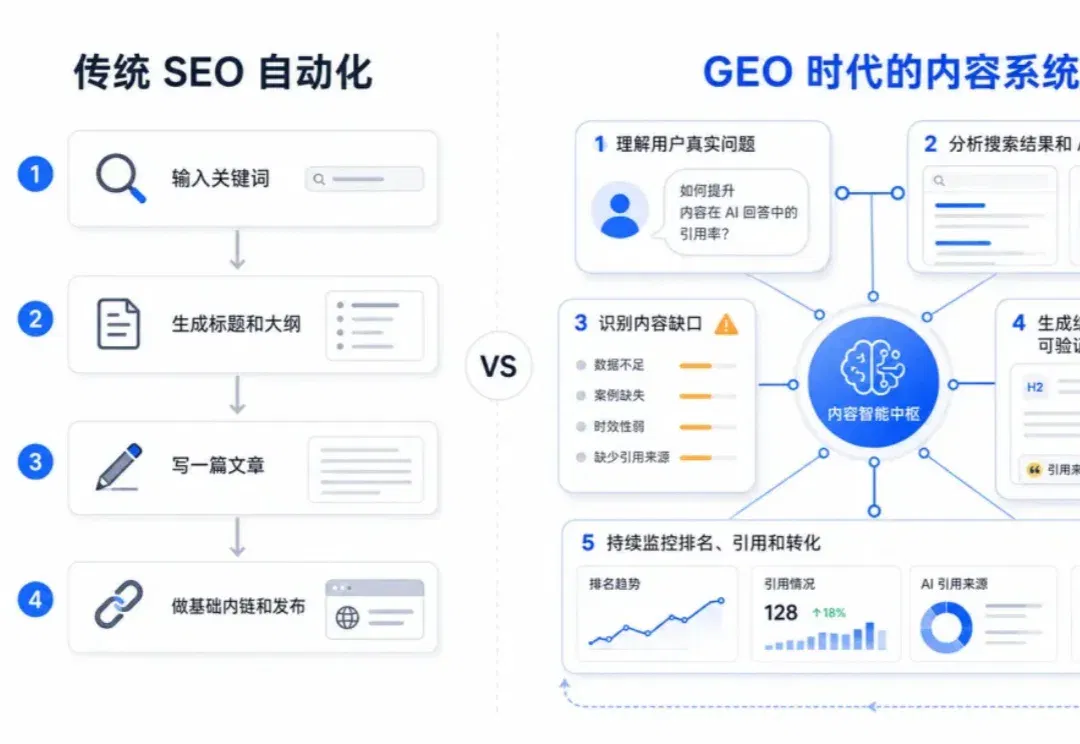
最近,有很多朋友来请教我们一个问题,GEO到底要怎么做,才能让生成的内容质量更高。
最近,有很多朋友来请教我们一个问题,GEO到底要怎么做,才能让生成的内容质量更高。
这个问题可以拆成两部分。
第一,怎么优化提示词,能让AI产出更精美,不带明显AI味儿的内容,这一般需要GEO公司内部的 know-how 积累。
第二,怎么辅助客户或者业务部门,建设知识库,让Agent 产出带着企业知识和历史经验的高质量内容。
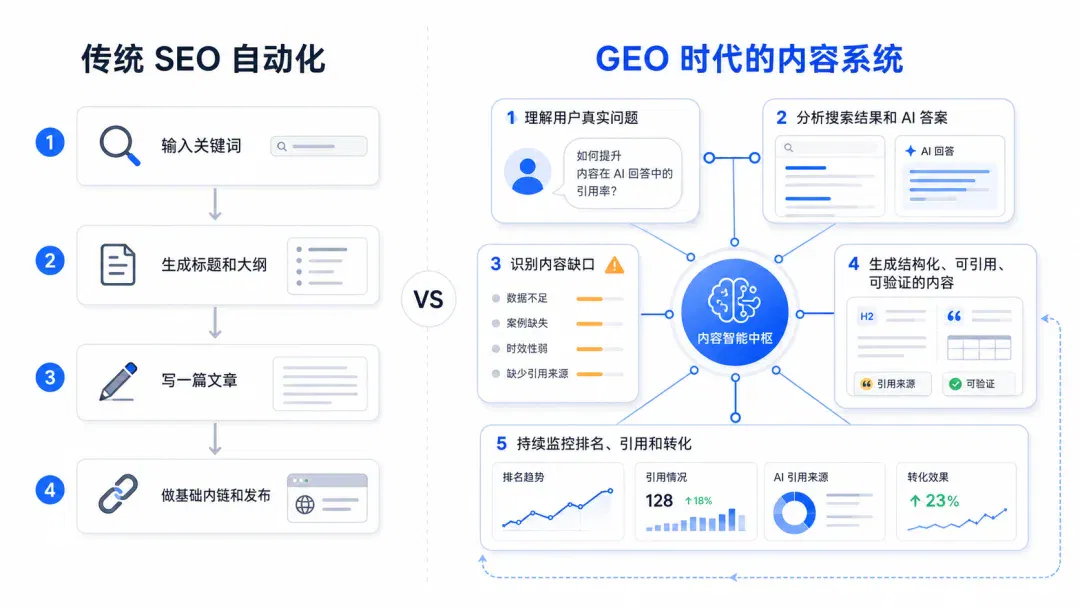
针对后一种情况,我们会建议用 Hermes 风格的 Agent 工程来组织 GEO Pipeline,并围绕 Milvus 建立企业的知识与记忆体系。
01
如何把 GEO 做成Agent 流水线
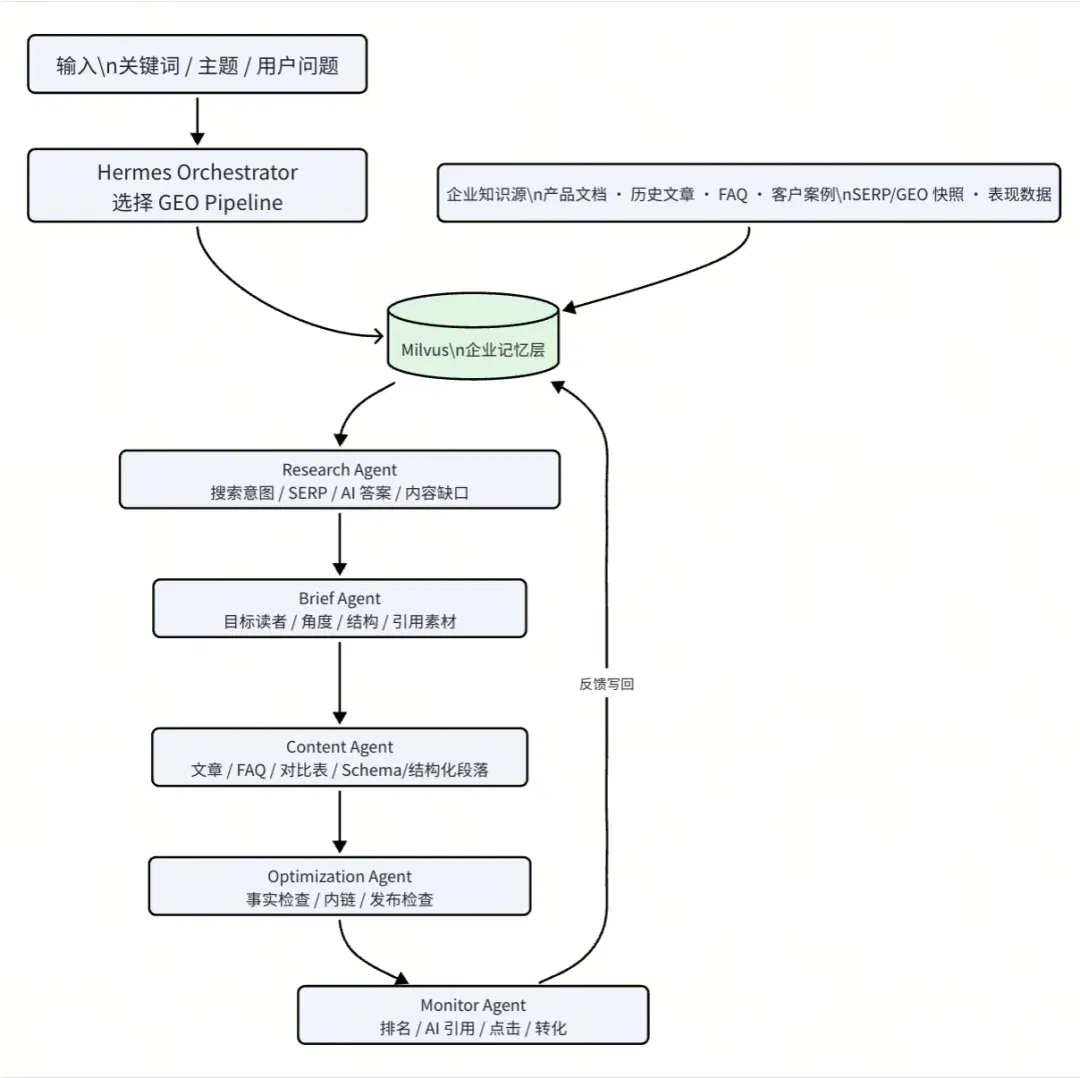
以下张图,是我们建议做GEO Hermes 的标准配置,整体可以分为两大模块。
模块一,决策模块:Orchestrator 判断任务类型,Research、Brief、Content、Optimization、Monitor 几个 Agent 按顺序推进。分别用于研究用户问题、生成内容 brief、生产结构化内容、质量检查、监控内容是否被搜索和 AI 答案引用并由 Orchestrator 编排成能共享上下文、工具和记忆连续工作流。
模块二,记忆模块,由Milvus 在中间做企业记忆层,存放产品文档、历史文章、FAQ、客户案例、可选的 SERP/GEO 快照和表现数据。每个 Agent 需要上下文时,都从同一套记忆里检索;监控阶段拿到的新结果,也会继续写回去。
02
Hermes GEO Pipeline 搭建教程
接下来,我们用 OpenAI embedding、Milvus 和一个最小 Hermes Orchestrator,搭建一条可以运行的 GEO Pipeline。
(1)准备
依赖和环境
先安装需要的依赖。这里使用 OpenAI 生成 embedding,使用 Milvus Lite 在本地保存向量数据。
pip install "pymilvus[milvus_lite]" openai
设置 OpenAI API Key,并指定 embedding 模型。这里使用 text-embedding-3-small,向量维度设置为 512。
exportOPENAI_API_KEY="YOUR_OPENAI_API_KEY"
exportOPENAI_EMBED_MODEL="text-embedding-3-small"
exportOPENAI_EMBED_DIM="512"
准备 Agent Profile
Hermes 的核心是先把 Agent 的职责拆清楚。这个最小示例里,我们定义四个 Agent:Research、Brief、Content 和 Monitor。
COMPANY_BRAIN = {
"brand": "Milvus",
"audience": "AI engineers and platform teams",
"product": "open-source vector database for AI applications",
"voice": "technical, practical, evidence-based",
}
AGENT_PROFILES = {
"research": {
"goal": "derive search intent, user questions, and GEO gaps from company memory",
"sources": ["product_doc", "blog", "faq", "case_study", "geo_playbook"],
},
"brief": {
"goal": "turn research into an executable content brief",
"sources": ["product_doc", "blog", "faq", "case_study"],
},
"content": {
"goal": "draft structured content for SEO and GEO",
"sources": ["product_doc", "blog", "geo_playbook"],
},
"monitor": {
"goal": "write performance feedback back into memory",
"sources": ["performance_memory"],
},
}
准备企业记忆
真实的企业记忆可以来自产品文档、历史博客、FAQ、客户案例和内容表现数据;如果生产环境已经接入搜索 API,也可以把 SERP 快照和 AI 搜索答案作为额外记忆写入 Milvus。为了跑通流程,这里先准备几条短文本。
SEED_MEMORY = [
{
"text": "Zilliz Vector Lakebase is a semantic-centric data platform where open storage and elastic compute converge for AI workloads.",
"source": "product_doc",
"topic": "Vector Lakebase",
"content_type": "definition",
},
{
"text": "Vector Lakebase supports three workload modes: real-time retrieval for latency-critical serving, iterative discovery for multi-step exploration, and batch analytics for offline mining and dataset optimization.",
"source": "blog",
"topic": "Vector Lakebase",
"content_type": "explanation",
},
{
"text": "AI systems are no longer just a single-query retrieval problem; they operate as a continuous loop of serving, learning, and improving.",
"source": "faq",
"topic": "AI data foundation",
"content_type": "positioning",
},
{
"text": "A vector database mainly supports real-time retrieval, while Vector Lakebase adds interactive discovery and batch analytics on top of a unified semantic data plane.",
"source": "geo_playbook",
"topic": "Vector Lakebase",
"content_type": "comparison",
},
{
"text": "External Data Lake Search creates a zero-copy logical mapping from Zilliz to existing lake tables while enabling high-performance indexes and full-spectrum search.",
"source": "case_study",
"topic": "External Data Lake Search",
"content_type": "capability",
},
]
(2)将企业记忆加载到 Milvus
准备 embedding 模型
使用 OpenAI SDK 封装一个简单的 embedding 函数。后面写入 Milvus 和检索查询时都会调用它。
from __future__ import annotations
import hashlib
import os
from dataclasses import dataclass
from pathlib import Path
from typing import Iterable
from openai import OpenAI
from pymilvus import MilvusClient
ROOT = Path.cwd()
DEFAULT_DB = ROOT / "hermes_geo_memory.db"
COLLECTION = "hermes_geo_memory"
EMBED_MODEL = os.getenv("OPENAI_EMBED_MODEL", "text-embedding-3-small")
DIM = int(os.getenv("OPENAI_EMBED_DIM", "512"))
LLM_MODEL = os.getenv("OPENAI_LLM_MODEL", "gpt-4.1-mini")
defstable_id(text: str) -> int:
returnint(hashlib.md5(text.encode("utf-8")).hexdigest()[:12], 16)
classOpenAIEmbedder:
def__init__(self, model: str = EMBED_MODEL, dimensions: int = DIM):
ifnot os.getenv("OPENAI_API_KEY"):
raise RuntimeError("OPENAI_API_KEY is not set. Export it before running this notebook.")
self.client = OpenAI()
self.model = model
self.dimensions = dimensions
defembed(self, texts: list[str]) -> list[list[float]]:
response = self.client.embeddings.create(
model=self.model,
input=texts,
dimensions=self.dimensions,
)
return [item.embedding for item in response.data]
创建集合并插入数据
接下来创建一个 Milvus collection。每条记忆会保存向量,同时保留 source、topic 和 content_type 等 metadata,方便 Agent 后续按来源和主题检索。
classMemoryStore:
def__init__(self, uri: str, embedder: OpenAIEmbedder):
self.client = MilvusClient(uri)
self.embedder = embedder
defreset(self) -> None:
ifself.client.has_collection(COLLECTION):
self.client.drop_collection(COLLECTION)
self.client.create_collection(
collection_name=COLLECTION,
dimension=DIM,
metric_type="COSINE",
)
defadd(self, chunks: Iterable[dict]) -> None:
chunks = list(chunks)
vectors = self.embedder.embed([chunk["text"] for chunk in chunks])
rows = []
for chunk, vector inzip(chunks, vectors):
rows.append(
{
"id": stable_id(chunk["text"]),
"vector": vector,
**chunk,
}
)
if rows:
self.client.insert(collection_name=COLLECTION, data=rows)
(3)构建 Hermes GEO Pipeline
检索企业记忆
Research Agent 接到主题后,先从 Milvus 中检索相关的企业记忆。这里返回文本和 metadata,供后面的 Brief Agent 使用。
defsearch(self, query: str, sources: list[str] | None = None, limit: int = 5) -> list[dict]:
expr = None
if sources:
quoted = ", ".join([f'"{source}"'for source in sources])
expr = f"source in [{quoted}]"
query_vector = self.embedder.embed([query])[0]
results = self.client.search(
collection_name=COLLECTION,
data=[query_vector],
limit=limit,
filter=expr,
output_fields=["text", "source", "topic", "content_type"],
)
return [hit["entity"] for hit in results[0]]
编排 Agent 流程
最后,用 Orchestrator 把几个 Agent 串起来。流程是:Research 检索上下文,Brief 生成内容方向,Content 组织内容结构,Monitor 把反馈写回 Milvus。
@dataclass
classResearchResult:
topic: str
intent: str
memories: list[dict]
gaps: list[str]
defresearch_agent(topic: str, memory: MemoryStore) -> ResearchResult:
profile = AGENT_PROFILES["research"]
research_query = (
f"{topic}. Retrieve company knowledge that helps explain "
"search intent, user questions, and content gaps."
)
memories = memory.search(
research_query,
sources=profile["sources"],
limit=5,
)
return ResearchResult(
topic=topic,
intent="Help readers understand the topic and make a practical implementation decision.",
memories=memories,
gaps=[
"Explain the system architecture instead of only listing prompts.",
"Show where Milvus fits in the GEO pipeline.",
"Turn retrieved company memory into a reusable content brief.",
],
)
defbrief_agent(research: ResearchResult) -> str:
context = "\n".join(
[f"- [{item['source']}] {item['text']}"for item in research.memories]
)
gaps = "\n".join([f"- {gap}"for gap in research.gaps])
returnf"""Topic: {research.topic}
Audience: {COMPANY_BRAIN["audience"]}
Voice: {COMPANY_BRAIN["voice"]}
Search intent:
{research.intent}
Relevant company memory retrieved from Milvus:
{context}
Content gaps to cover:
{gaps}
Recommended structure:
1. Why prompt-only SEO automation is not enough
2. How a Hermes-style GEO pipeline works
3. Where Milvus provides memory and retrieval
4. Minimal implementation tutorial
5. Feedback loop for monitoring and updates
"""
defcontent_agent(brief: str) -> dict:
client = OpenAI()
prompt = f"""请根据下面的 GEO brief,写一篇中文技术文章。
写作要求:
- 开头直接回答标题里的核心问题,不要绕太远。
- 解释 Zilliz Vector Lakebase 是什么,以及为什么 AI Agent 不只需要 real-time retrieval。
- 自然说明 Milvus / Zilliz 在这条 GEO Pipeline 里的位置,不要写成硬广。
- 保留工程视角:系统怎么组织、记忆层怎么用、为什么要反馈写回。
- 加一个 FAQ 小节,覆盖 AI 搜索可能引用的直接问答。
- 语气像微信技术文章,具体、克制、少用口号。
- 输出 Markdown。
GEO brief:
{brief}
"""
response = client.chat.completions.create(
model=LLM_MODEL,
messages=[
{
"role": "system",
"content": "You write practical Chinese technical articles for AI engineers.",
},
{"role": "user", "content": prompt},
],
temperature=0.4,
)
article = response.choices[0].message.content or""
return {
"brief": brief,
"article": article.strip(),
}
defmonitor_agent(topic: str, memory: MemoryStore) -> None:
memory.add(
[
{
"text": (
f"Pipeline generated a GEO brief for {topic}. "
"After publishing, track AI citations, organic clicks, and assisted conversions."
),
"source": "performance_memory",
"topic": topic,
"content_type": "feedback",
}
]
)
defrun_pipeline(topic: str, db_uri: str, reset: bool) -> dict:
embedder = OpenAIEmbedder()
memory = MemoryStore(db_uri, embedder)
if reset:
memory.reset()
memory.add(SEED_MEMORY)
print("== Hermes GEO Pipeline ==")
print(f"Topic: {topic}")
print(f"Embedding model: {EMBED_MODEL} ({DIM} dims)")
print()
print("[1/4] Research Agent: retrieving company memory from Milvus...")
research = research_agent(topic, memory)
print(f"Retrieved {len(research.memories)} memory chunks.")
print()
print("[2/4] Brief Agent: turning memory into a content brief...")
brief = brief_agent(research)
print("Brief generated.")
print()
print("[3/4] Content Agent: writing the GEO article...")
draft = content_agent(brief)
print("Article generated.")
print()
print("[4/4] Monitor Agent: writing feedback back to Milvus...")
monitor_agent(topic, memory)
print("Feedback stored.")
print()
print("== Generated GEO Article ==")
print(draft["article"])
return draft
(4)运行 Pipeline
运行后,可以看到 Research Agent 先从 Milvus 中检索 Vector Lakebase 相关的企业记忆,然后 Brief Agent 将这些记忆整理成内容方向,Content Agent 再生成完整的 GEO 文章。
topic = "What is Zilliz Vector Lakebase, and why do AI agents need more than real-time retrieval?"
db_uri = str(DEFAULT_DB)
draft = run_pipeline(topic=topic, db_uri=db_uri, reset=True)
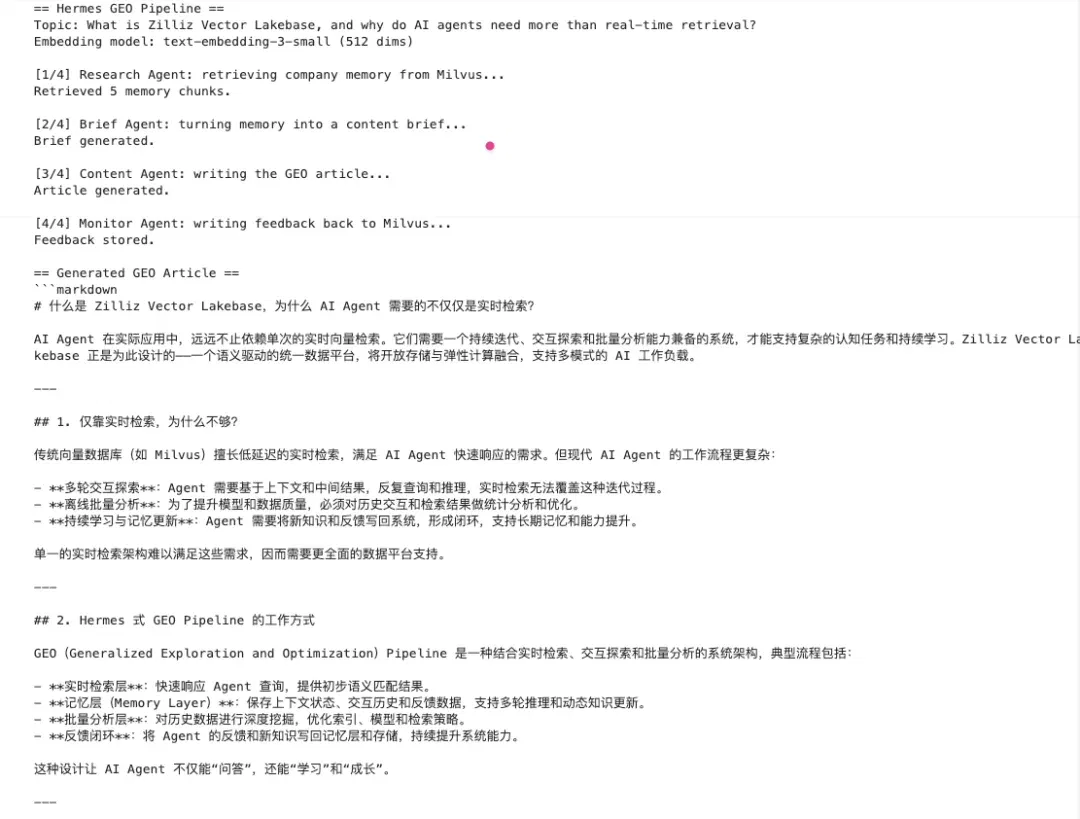
需要说明的是本文是一个最小版本的Hermes-style Pipeline,用来演示 Research、Brief、Content、Monitor 这些步骤如何串起来。如果希望它真正由 Hermes Agent 编排,需要先安装 Hermes CLI,并把GEO流程封装成Hermes可调用的skill、tool 或者脚本。
作者介绍
王舒虹
Zilliz Social Media Advocate
文章来自于"Zilliz",作者 "王舒虹"。
Related topics
After reading
Join the AINRK community
Read how to join the community and connect with people working in AI.
Related articles
Continue reading related topics and articles in this category.
你不知道的 GEO:AI 可见性的原理、实践与取舍 (opens in a new tab)
这几天有好几个小伙伴@我说,我的开源工具在他们问 AI 的时候被主动推荐了,啥也没做居然可以被收录,想着要不花一个小时把内容结构化整一整,应该会更好,于是整好以后,快速发了一个速记推,但是内容结构不清晰,想着大家很感兴趣,那要不就整一个结构清晰的文章便于沉淀和查找。
SEO已死,GEO当立!啃完普林斯顿论文,我挖到了8条神级打法。 (opens in a new tab)
大家好,我是袋鼠帝。 今天想跟大家聊聊最近很火的一个新概念:GEO
蚂蚁与西湖心辰介绍Duo v1,探索全双工视听交互 (opens in a new tab)
Duo v1通过Intent与Realization模块衔接交互决策和音视频生成。文章报告30组交互、180项检查中通过168项,内容响应度为73.3%;复杂意图理解与长程一致性仍是团队后续优化方向。
EgoExplorer captures mobile manipulation with five trackers and a camera (opens in a new tab)
Shanghai AI Lab presents a wearable capture system using trackers, gloves and a camera, plus C³ motion reconstruction, and releases 100 hours of data and code. Reconstruction and multimodal generation are assessed separately; humanoid transfer is shown only in simulation.

ConvexLLM connects speech to language models through frozen text embeddings (opens in a new tab)
Researchers at CUHK-Shenzhen and Microsoft propose C-Gate, mapping audio into convex combinations of frozen text embeddings. The paper reports VoiceBench gains against its listed open-model baselines, while audio understanding and transcription still involve trade-offs.